AI Fundamentals
What Is Emotion AI (Affective Computing), and Why Does It Matter?

 Add Unite.AI to your preferred sources on Google
Emotion AI, often called affective computing, applies computation to signals associated with affect, such as language, vocal prosody, facial movement, posture, physiology, or interaction patterns. A system may classify a label, estimate dimensions such as valence and arousal, or adapt an interface.
The output is an inference—not a direct reading of an inner emotional state. Expressions vary by person, culture, context, health, and situation, so the same observable signal can support several explanations. High-stakes uses require strong evidence, consent, and legal review.
Key takeaways
- Define the observable target precisely; emotion, expression, sentiment, stress, and engagement are not interchangeable.
- Validate on the intended population and environment, not only a curated benchmark.
- Prefer assistance and user control over hidden surveillance or consequential automated judgment.
- Document uncertainty, data rights, retention, subgroup performance, and a path to contest decisions.
Signals and model targets
Text models can estimate expressed sentiment; audio models use timing, pitch, and energy; vision models analyze movements; physiological systems may use heart rate or skin conductance. Multimodal systems combine signals, but more sensors do not automatically produce a truer label.
A label such as ‘frustrated’ depends on annotation instructions and context. Sentiment analysis of words is narrower than inferring a person’s emotional condition, and neither should be confused with clinical assessment.
Why context and uncertainty dominate
People mask, exaggerate, or express feelings differently. Disability, language, lighting, microphone quality, and social norms can change observed signals. Lab datasets may not represent a call center, classroom, vehicle, or clinic.
Evaluate calibration, abstention, per-group errors, cross-domain performance, and alternatives. Confusion matrices help show which labels are mixed up, but qualitative review is needed to understand why.
Useful and risky applications
User-controlled applications can support accessibility, reflective journaling, adaptive training, or a safety alert. These uses should make clear what is measured, allow correction, and avoid overstating certainty.
Employment, education, insurance, policing, and health decisions create much higher stakes. The EU AI Act prohibits certain emotion-recognition uses in workplaces and education, subject to specified exceptions, and classifies other uses according to risk. Requirements vary by jurisdiction and change over time.
Responsible deployment
Ask whether the task needs an emotion inference at all. Use data minimization, explicit purpose, short retention, security, independent testing, user notice, and human review. Avoid building secondary profiles from signals collected for another purpose.
Apply explainable-AI practices without suggesting that a saliency map proves an emotion. Communicate uncertainty in plain language and provide a meaningful way to opt out or challenge a consequential result.
How affect is represented
Categorical models predict labels such as joy, anger, fear, sadness, or neutral. Dimensional models estimate continuous values such as valence, arousal, and dominance. Appraisal models describe how a person evaluates an event. These representations are theories and measurement choices, not interchangeable ground truth.
Annotations may come from the person experiencing the event, an observer, a clinician, or an experimental protocol. Self-report has introspective and recall limits; observer labels infer state from behavior; physiological measurements reflect arousal and many non-emotional processes. A dataset should state whose perspective the label represents.
Temporal modeling is important because affect unfolds over time. Frame-level facial labels can overreact to transient movement, while an utterance-level average can hide change. Window length, synchronization across sensors, missing channels, and speaker baselines affect the result.
Modeling pipelines by modality
Vision pipelines detect and align faces or bodies, extract frames or landmarks, then classify spatial and temporal features. Occlusion, camera angle, compression, skin tone, glasses, facial difference, and deliberate expression can alter performance. Facial action units describe movement more directly than an asserted emotion and may be the safer target.
Audio pipelines separate speech, normalize level, and model spectral, prosodic, and temporal patterns. A raised pitch may indicate excitement, stress, a question, or speaker habit. Text pipelines capture expressed evaluation and context but lose tone unless combined with audio. Multimodal fusion can occur at feature, decision, or cross-attention layers.
Personalization may calibrate to an individual’s baseline, but it requires more data and creates a sensitive longitudinal profile. Systems should prefer local or short-lived adaptation where possible and must avoid using one person’s data to make unrelated inferences without a valid purpose.
Evaluation, human factors, and safeguards
Randomly splitting frames from the same video across training and test creates leakage. Hold out people, sessions, devices, sites, and time periods according to the intended claim. Report macro metrics so common classes do not hide failure on rare states, and include an abstain option for ambiguous input.
User studies should measure whether adaptation actually helps. An interface that changes tone based on an incorrect inference can feel intrusive or patronizing. Let users correct the system, choose the degree of adaptation, and see the functional reason for a response without being assigned a definitive emotional label.
High-risk deployment needs an impact assessment, legal review, security, and a ban on secondary uses. Store raw video or biometrics only when necessary, limit access, and define deletion. Do not use emotion scores as sole evidence for deception, performance, competence, intent, or mental health.
Evaluating an emotion-AI use case before deployment
Start by defining the claimed construct: facial movement, vocal prosody, self-reported feeling, observed behavior, or a clinical state are not interchangeable. Identify the decision that will use the output and whether a less intrusive signal can serve it. A system that adapts game difficulty to explicit frustration feedback has a different evidence and risk profile from one that infers employee honesty from a webcam.
Validation needs representative people, cultures, languages, devices, contexts, and recording conditions, with ground truth appropriate to the claim. Compare against simple baselines and report uncertainty, subgroup error, inter-rater disagreement, and performance outside the lab. Do not convert a probabilistic score into a categorical statement about what a person feels. Give users correction, opt-out, and a non-biometric path where feasible.
Prohibit consequential decisions based solely on inferred emotion, especially in employment, education, insurance, policing, healthcare, and access to services. Minimize raw audio and video retention, isolate biometric identifiers, and control secondary use. Documentation should explain training context, intended use, invalid uses, and known confounders such as disability, masking, stress, culture, or medication. Emotion AI is a measurement claim that requires evidence, not a magical window into internal experience.
Practical implementation checklist
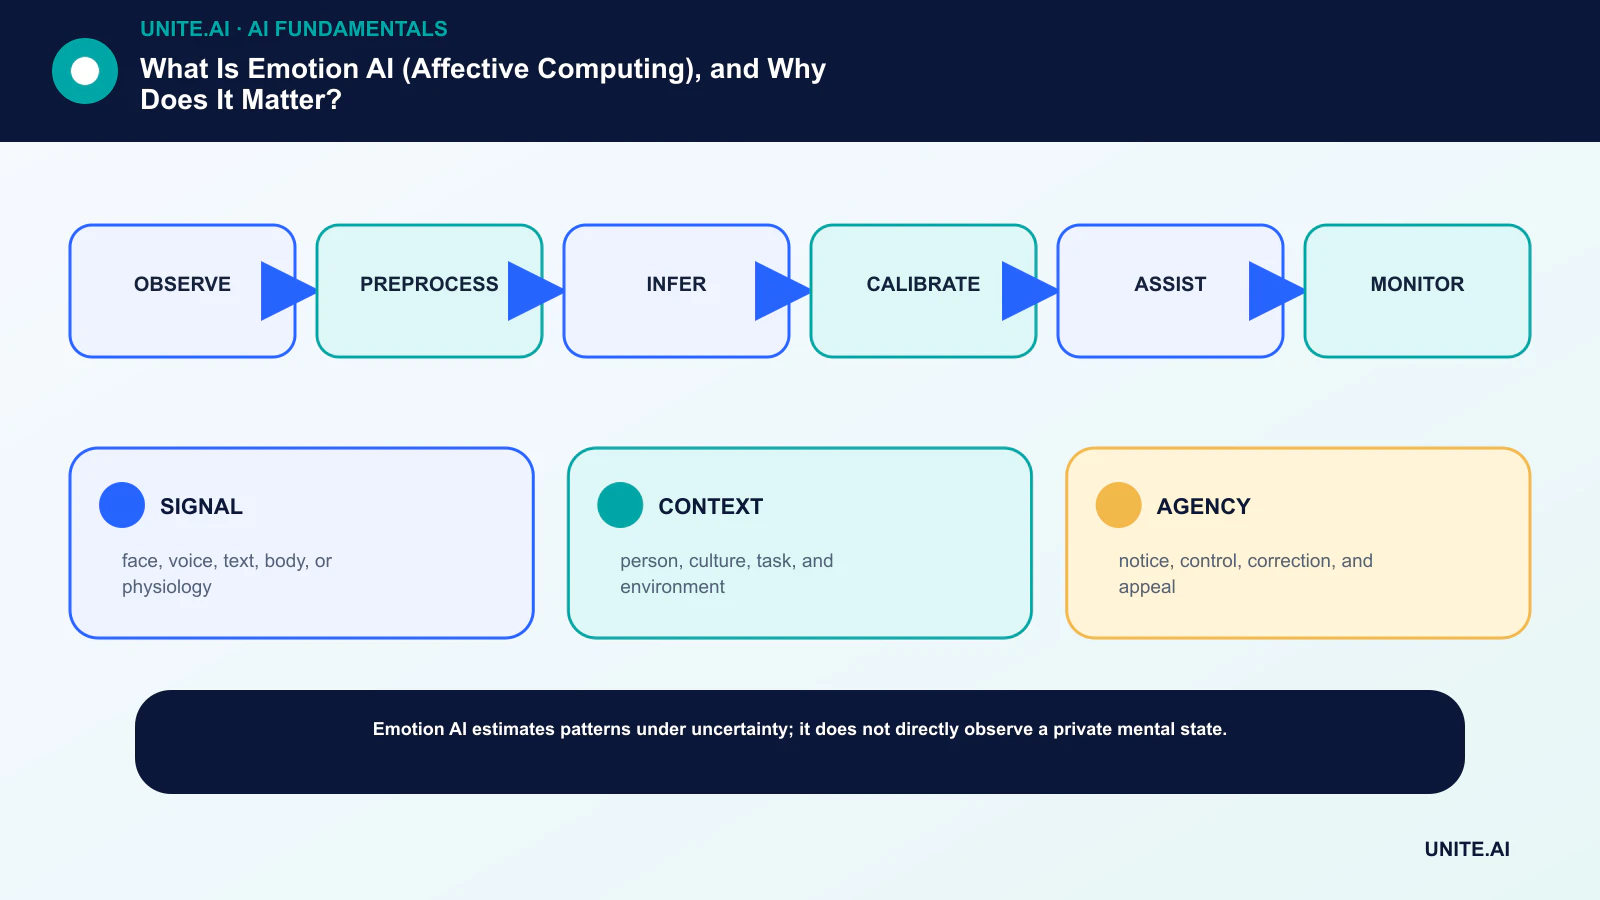
Turn the concept into a bounded, testable workflow: observe → preprocess → infer → calibrate → assist → monitor. Name an accountable owner, document the data and dependencies, establish a simple baseline, set acceptance and stop criteria, test representative failures, and define monitoring, rollback, and review before expanding scope. Record versions and assumptions so another team can reproduce the result and understand what changed.
Before launch, run a documented readiness review with the people who build, operate, secure, and are affected by the system. Test normal cases, boundary conditions, dependency failures, and misuse; preserve the evidence and unresolved risks. Define who can approve release, change a threshold, override an output, or stop operation. Revisit the decision after real-world data arrives, because a technically successful pilot does not guarantee reliable performance at broader scale.
- SIGNAL: face, voice, text, body, or physiology.
- CONTEXT: person, culture, task, and environment.
- AGENCY: notice, control, correction, and appeal.
Frequently asked questions
Can AI accurately read emotions from a face?
It can predict dataset labels from facial movements, but those movements do not uniquely determine an internal emotion. Accuracy depends strongly on context, population, labels, and measurement design.
Is emotion AI legal?
It depends on the use, data, people, and jurisdiction. Some contexts are prohibited or high-risk. Organizations need current legal advice, not a generic technical checklist.
Primary references