AI Fundamentals
What Is a Data Warehouse? Architecture, ETL, and Use Cases

 Add Unite.AI to your preferred sources on Google
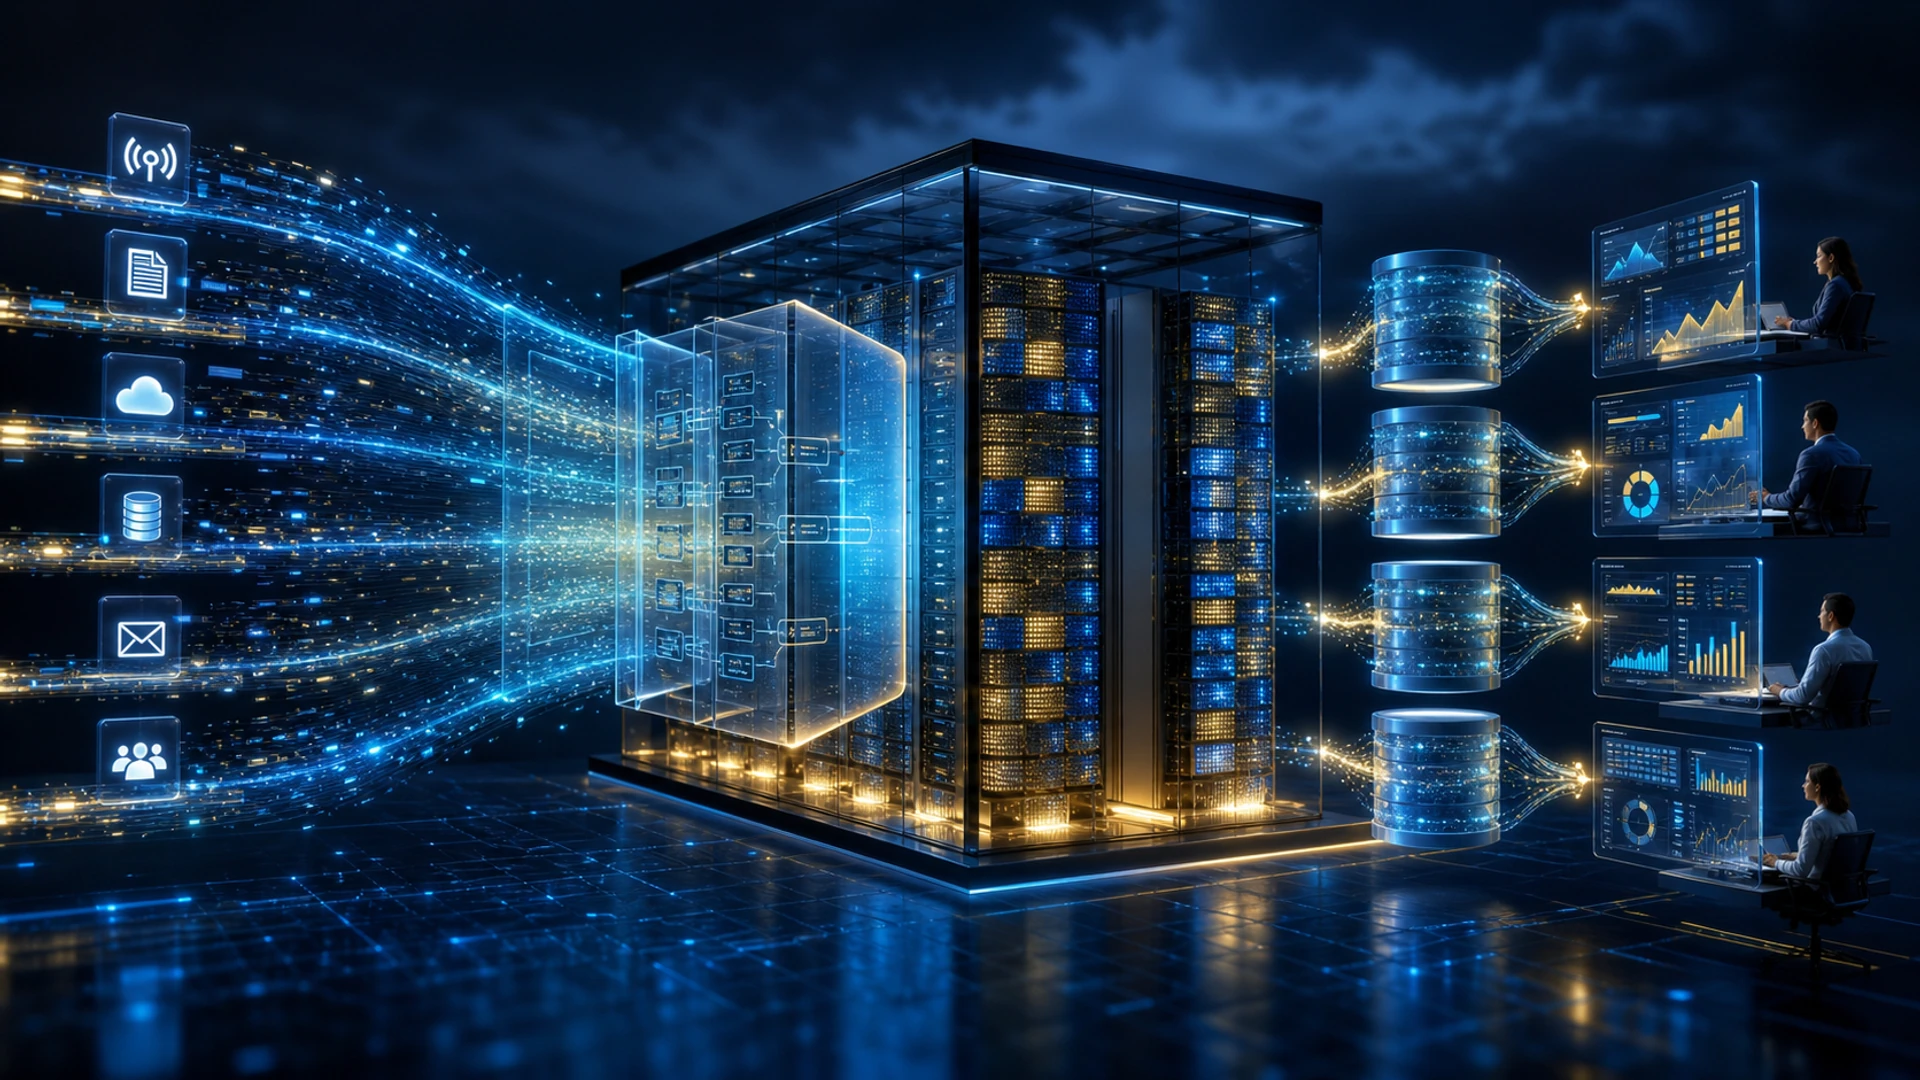
A data warehouse is an analytical data system that integrates information from operational sources and organizes it for reporting, business intelligence, and repeatable analysis. It separates many analytical workloads from the applications that record transactions.
Modern warehouses may be columnar, distributed, serverless, or connected to object storage. The defining work remains consistent: governed ingestion, modeled meaning, history, query performance, security, quality, and reliable delivery to users.
Key takeaways
- Operational systems optimize current transactions; warehouses optimize historical analysis across sources.
- ETL transforms before loading, while ELT loads first and transforms inside the analytical platform.
- Dimensional, normalized, and wide-table models serve different workloads and governance needs.
- Trust depends on lineage, tests, freshness, access control, semantic definitions, and cost monitoring.
Sources, ingestion, and storage
Data can arrive through batches, change-data capture, streams, files, and APIs. A landing layer preserves source context; transformations standardize types, deduplicate records, handle late events, and create reusable analytical entities.
This extends the ETL workflow. ELT uses warehouse compute for transformation, while ETL can reduce or validate data before loading. The right choice depends on latency, privacy, scale, and toolchain.
Model data for questions
Dimensional models organize measurable facts around descriptive dimensions such as customer, product, and time. Normalized core models can preserve enterprise relationships, while denormalized marts simplify common queries.
A semantic layer gives metrics consistent definitions. Without it, teams can produce several valid-looking revenue or retention figures from the same rows. Structured data still requires agreed meaning.
Warehouse, lake, and lakehouse
A data lake typically stores files and diverse raw or processed data in object storage. A warehouse supplies managed analytical tables and query services. Lakehouse designs add table metadata, transactions, and governance to lake storage.
These are architectural patterns, not guarantees. Organizations often combine them through a data fabric or shared governance layer. Workload, skill, interoperability, and lifecycle cost matter more than the label.
Quality, security, and operations
Define owners, contracts, freshness targets, lineage, tests, retention, and row or column access. Separate personally identifiable data, use least privilege, and audit sensitive queries. Backfills and schema changes need controlled, observable procedures.
Measure successful refreshes, data delay, test failures, query performance, adoption, incident impact, and cost per workload. A warehouse is useful when people can trace a metric to governed data and reproduce the result.
Dimensional modeling and semantics
A fact table records events or periodic measurements at a declared grain, such as one order line or one device per hour. Dimensions provide descriptive context. Declaring grain before selecting columns prevents mixing levels that cause double counting. Additive measures can be summed across all dimensions; semi-additive measures need care across time.
Surrogate keys decouple warehouse history from changing source identifiers. Slowly changing dimensions define how attribute changes are handled: overwrite, preserve a new historical row, or keep limited prior values. The correct method follows the analytical question and retention obligations.
A semantic metric should define formula, filters, time behavior, currency, exclusions, owner, and tests. Central definitions reduce inconsistency, but governance should allow proposed changes and versioning. A single semantic layer becomes a bottleneck if users cannot inspect or extend it responsibly.
Modern storage and query architecture
Columnar storage keeps values of a column together, improving compression and scanning only needed fields. Partitioning prunes large sections by date or another key; clustering colocates related values; materialized views and caches reuse results. Poor partition choices create tiny files, skew, or expensive full scans.
Massively parallel query engines divide scans, joins, and aggregations across workers. Data movement during joins can dominate runtime, so distribution, statistics, and join order matter. Autoscaling and serverless services simplify capacity but require cost controls, workload priorities, and limits on runaway queries.
Lakehouse table formats add metadata, snapshots, schema evolution, and transaction semantics over object files. They improve interoperability but introduce catalog and maintenance responsibilities. Open formats reduce lock-in only when compute engines, governance, and operational procedures can actually use them.
Reliable pipelines and data products
Pipelines should be idempotent or able to reconcile duplicates. Watermarks and event time handle late arrivals; backfills reproduce historical transformations; schema contracts define compatible changes. Data tests cover uniqueness, completeness, accepted values, relationships, and business invariants—not just whether a job ran.
Treat important datasets as products with owners, documentation, service expectations, discoverability, support, and users. Lineage connects source fields through transformations to reports, making change impact and incident investigation faster. Access policies should propagate or be re-evaluated when data is copied.
A warehouse program succeeds when decisions become more reliable and faster, not when storage volume grows. Retire unused tables, expose query and storage cost, review sensitive access, and measure whether teams trust and reuse governed metrics instead of maintaining private spreadsheets.
Worked example: designing a sales analytics warehouse
Define the fact grain as one completed order line, then link product, customer, channel, promotion, geography, and date dimensions through surrogate keys. Keep order status events in a separate fact table rather than mixing snapshots and transactions. Revenue, quantity, discount, tax, and cost need explicit currency, return, cancellation, and recognition rules. The metric definition should produce the same answer in dashboards, notebooks, and finance reconciliation.
Ingestion captures source changes, lands immutable raw data, validates schema, and transforms it into tested staging and dimensional models. Late-arriving updates must correct the appropriate historical period without duplicating facts. Compare row counts and monetary totals with source systems, test uniqueness and relationships, and record lineage from report field to source. Backfills use versioned code and isolated validation before replacing trusted tables.
Access separates customer identifiers from broadly available aggregates and applies least privilege by role and purpose. Workload management keeps executive dashboards responsive while analysts run exploratory queries. Monitor freshness, failed tests, query cost, unused tables, and semantic changes. A warehouse is successful when governed metrics support repeatable decisions; merely centralizing data can centralize confusion if ownership, quality, and definitions remain unresolved.
Disaster recovery should specify backup coverage, cross-region copies, catalog and permission restoration, acceptable data loss, and recovery time. Test restoration into an isolated environment and verify metrics, not just files. Encryption keys, identity configuration, orchestration code, and semantic definitions are part of the recoverable system. A warehouse that can restore petabytes but cannot reproduce access policy or trusted calculations has not recovered its analytical service.
Practical implementation checklist
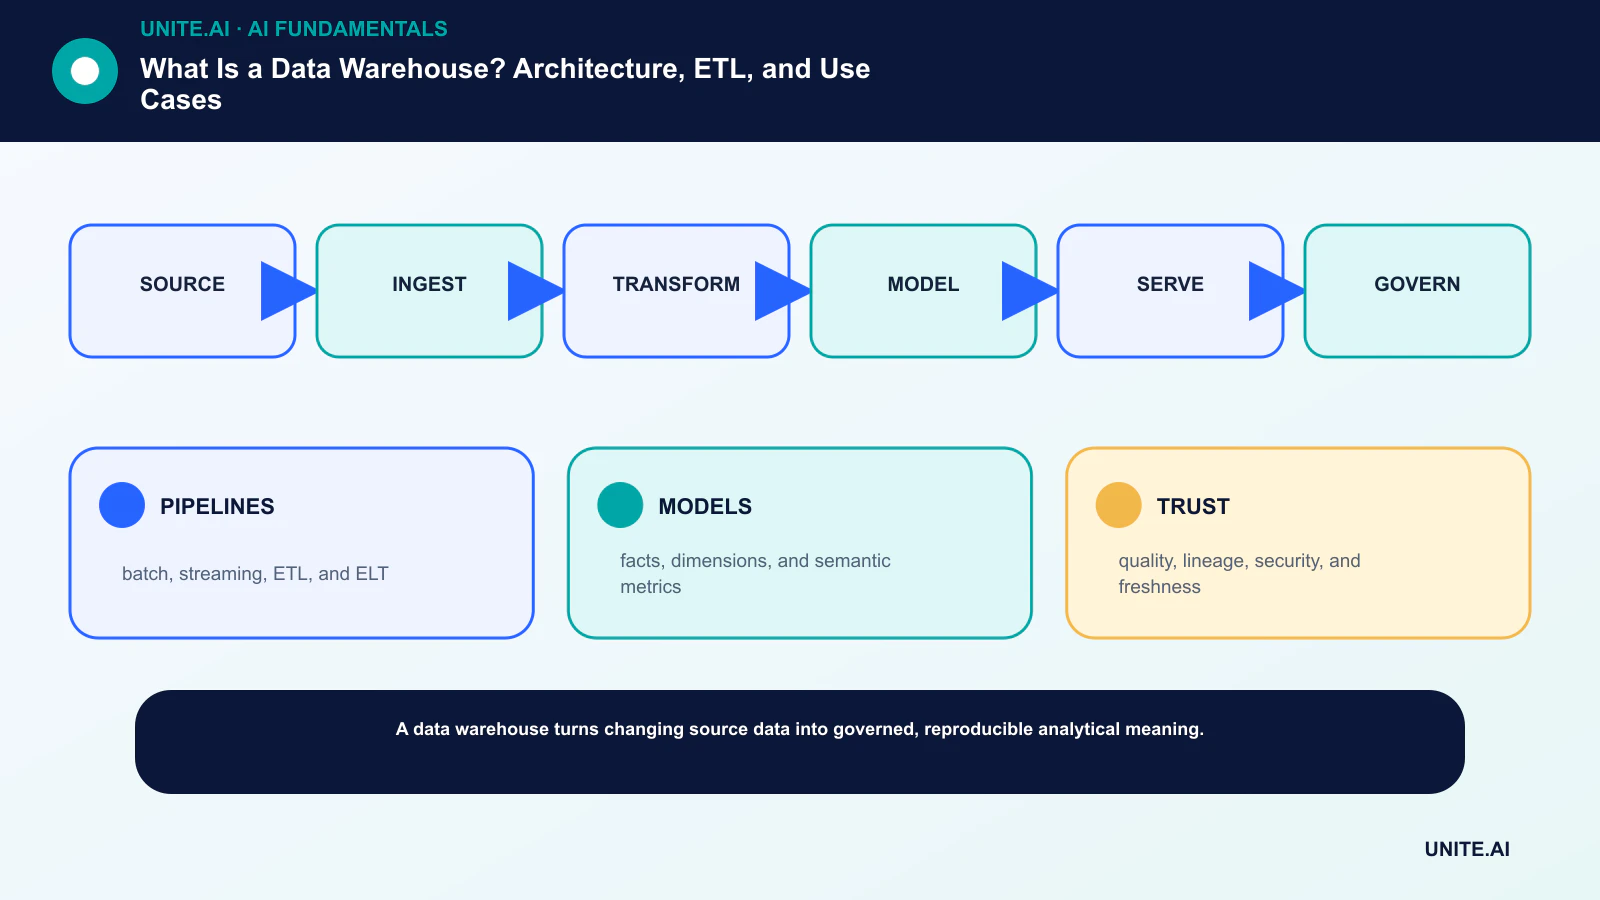
Turn the concept into a bounded, testable workflow: source → ingest → transform → model → serve → govern. Name an accountable owner, document the data and dependencies, establish a simple baseline, set acceptance and stop criteria, test representative failures, and define monitoring, rollback, and review before expanding scope. Record versions and assumptions so another team can reproduce the result and understand what changed.
Before launch, run a documented readiness review with the people who build, operate, secure, and are affected by the system. Test normal cases, boundary conditions, dependency failures, and misuse; preserve the evidence and unresolved risks. Define who can approve release, change a threshold, override an output, or stop operation. Revisit the decision after real-world data arrives, because a technically successful pilot does not guarantee reliable performance at broader scale.
- PIPELINES: batch, streaming, ETL, and ELT.
- MODELS: facts, dimensions, and semantic metrics.
- TRUST: quality, lineage, security, and freshness.
Frequently asked questions
Is a data warehouse just a large database?
It is a database or analytical platform designed around integrated, historical analysis. Its modeling, ingestion, governance, and workload patterns differ from a transactional application database.
Should a company use ETL or ELT?
Many use both. Transform early when privacy, validation, or bandwidth requires it; transform after loading when warehouse compute and rapid iteration are advantageous.
Primary references