AI Fundamentals
What is ETL? Extract, Transform, Load Explained

 Add Unite.AI to your preferred sources on Google
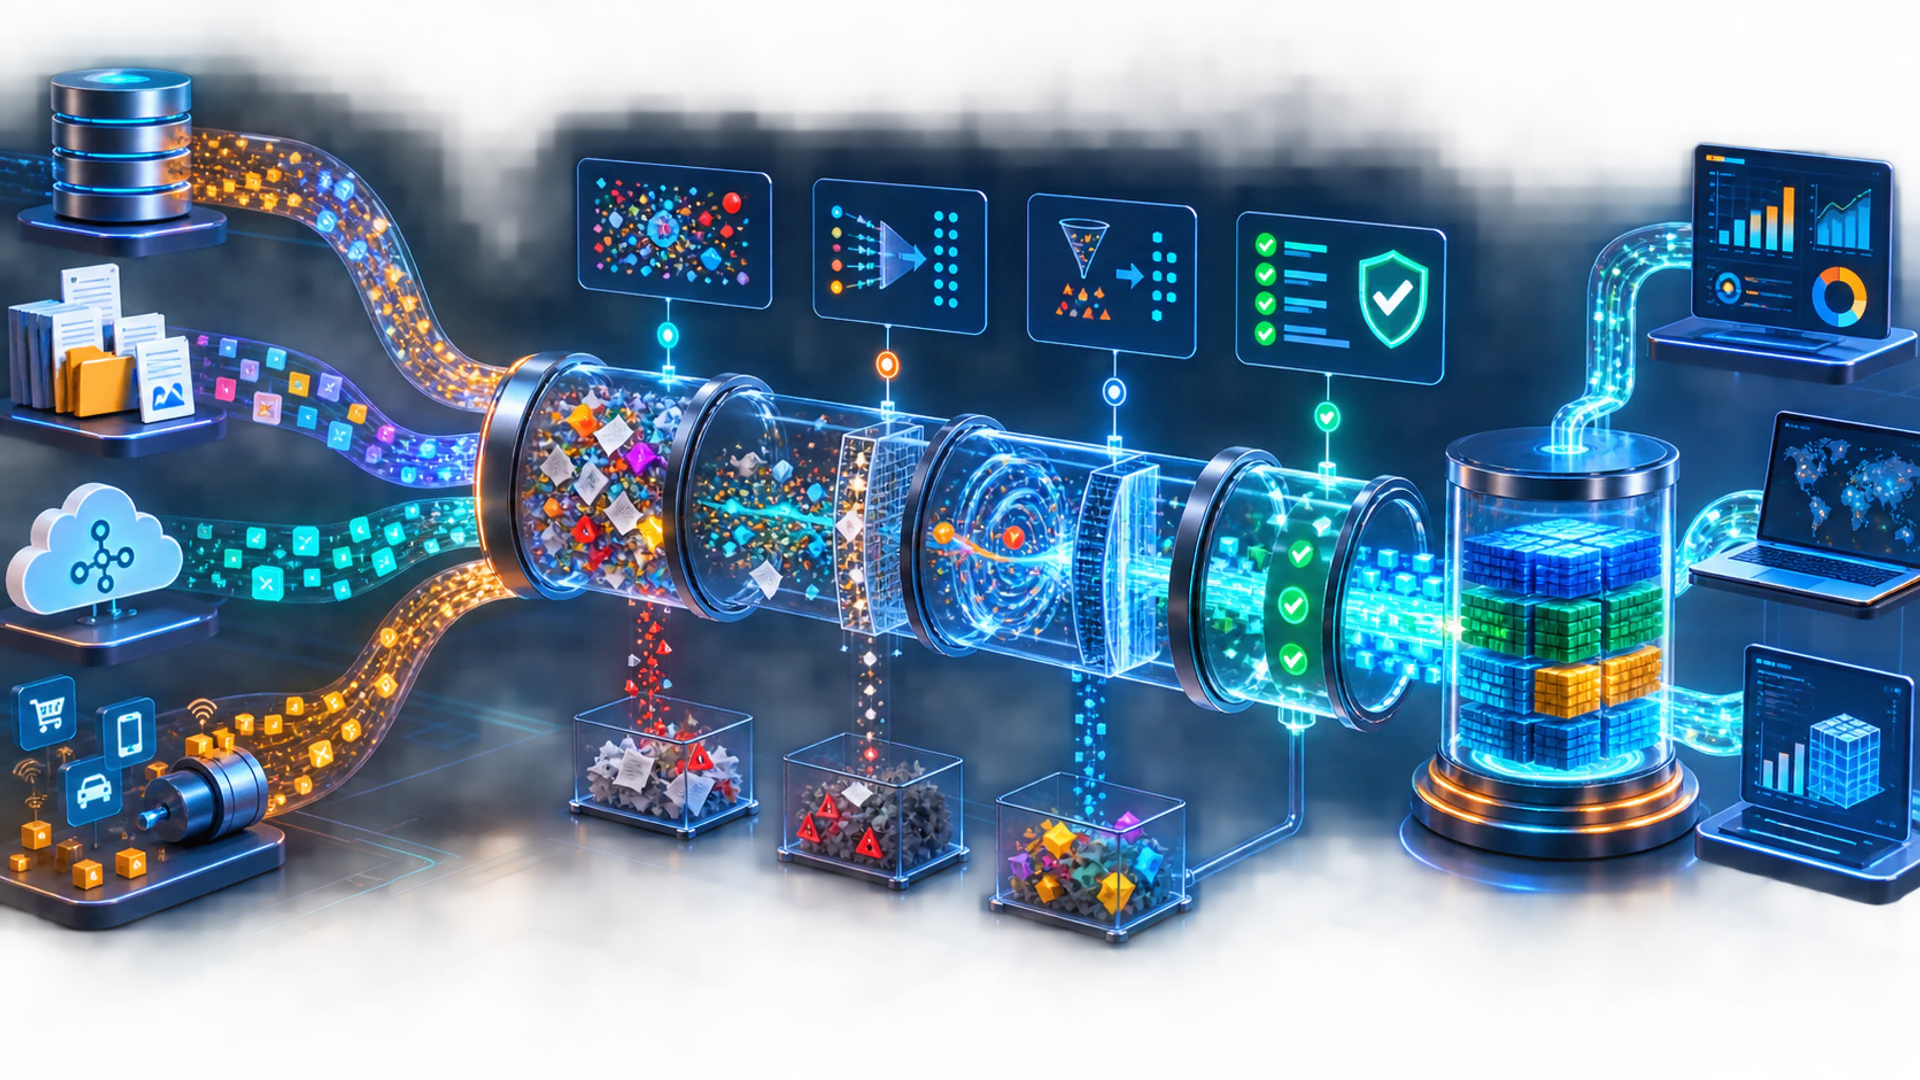
ETL—extract, transform, load—is a data-integration pattern that reads data from source systems, validates and reshapes it, then writes it into a destination suited to analytics, reporting, machine learning or operations.
A production ETL pipeline is more than three boxes. It needs repeatable execution, schema and quality controls, lineage, orchestration, observability, security and a safe way to backfill or replay data when logic changes.
Key takeaways
- Extraction should minimize source impact and record what interval or change set was captured.
- Transformations encode business meaning, so they need version control, tests and ownership.
- Loads should be idempotent or otherwise protect against duplicates and partial failure.
- ETL versus ELT is mainly about where transformation runs; modern systems often use both.
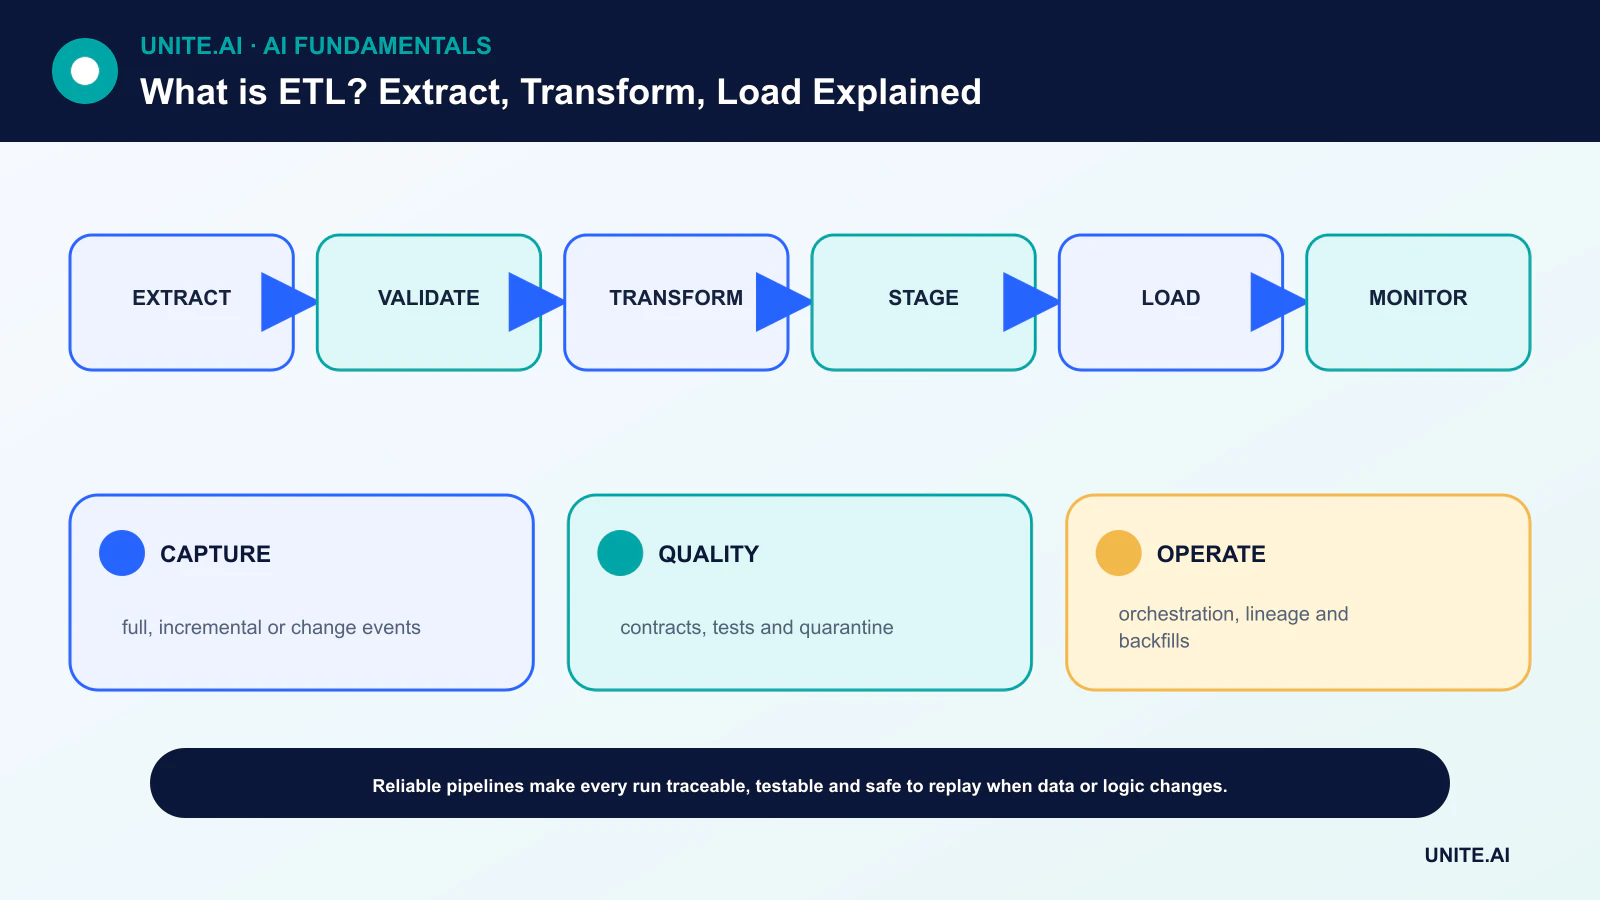
Extract data reliably
Sources can include databases, files, APIs, event streams and applications. A full extract copies a complete set; an incremental extract reads records changed since a checkpoint. Change-data capture consumes database logs or events to reduce repeated scans.
Record source identifiers, time boundaries and checkpoints. Respect rate limits and transaction semantics. If a source changes schema silently, fail safely or quarantine records rather than loading ambiguous data as if nothing happened.
Transform with explicit contracts
Transformations standardize types and units, parse records, join sources, remove or flag duplicates, apply business rules and calculate features. Separate invalid data from missing but acceptable data, and retain enough evidence to trace an output back to its inputs.
Version transformations in the same disciplined way as software delivery. Tests should cover schema, ranges, referential integrity, expected distributions and known examples. A data contract defines expectations between producer and consumer.
Load safely and repeatably
A load may append events, merge changed records, replace a partition or rebuild a table. Idempotence means rerunning the same input produces the same destination state. Transactions, staging tables and atomic swaps reduce exposure to partial updates.
Partitioning and indexing should match consumption patterns. Protect sensitive fields and apply destination permissions before data becomes queryable. Retention and deletion requirements must travel with the data.
ETL, ELT, batch and streaming
Traditional ETL transforms in a separate engine before loading. ELT loads raw or lightly processed data first, then uses destination compute for transformation. A cloud warehouse or lakehouse can make ELT convenient, but it does not remove quality or governance work.
Batch pipelines process bounded intervals; streaming pipelines process ongoing events with defined time and ordering semantics. Many architectures use streaming ingestion followed by periodic reconciliation, because late or corrected data are normal.
Orchestration, lineage and observability
An orchestrator schedules tasks, respects dependencies, retries defined failures and records state. Retries need limits and idempotent tasks. Backfills should be isolated and capacity-aware so historical repair does not disrupt current data.
Monitor freshness, volume, schema, quality, duration and cost. Lineage and the metadata layer of a data fabric help consumers understand which version produced a dataset and what broke upstream.
Extract: sources, contracts, and incremental capture
ETL moves data from source systems, transforms it into governed structures, and loads a destination. Extraction can use files, database queries, APIs, logs, streams, or change-data capture. Define source ownership, schema, keys, timestamps, timezone, units, deletion semantics, and allowed load. Full extracts are simple but expensive; incremental capture reduces volume but needs watermarks, log positions, or version fields and a strategy for late and corrected records.
Do not assume an API success means a complete extract. Record counts, checksums, sequence gaps, pagination, rate limits, retries, and source snapshots. Store immutable raw data where policy permits so transformations can be replayed. Protect credentials and sensitive fields, and make retries idempotent. Schema changes should be classified as compatible or breaking through contracts rather than discovered when a downstream dashboard silently changes.
Transform and load with reproducible semantics
Transformations parse types, standardize units, deduplicate, join, apply business rules, manage history, and derive facts and dimensions. Each rule needs tests and lineage. Fit statistical preprocessing only on appropriate training data when ETL feeds ML. Slowly changing dimensions determine whether attribute changes overwrite or preserve history. Declare fact grain before joining; many-to-many errors create duplicated measures that can survive basic row checks.
Loading may append, merge, replace partitions, or update records. Use staging tables and atomic swaps where possible so readers do not see partial state. Enforce uniqueness, relationships, accepted values, completeness, and business invariants. Handle late events and backfills with event time and versioned code. Reconciliation against source totals is essential for financial and operational data. ELT loads raw data before transformation in the destination; the governance and correctness requirements remain.
Operations and recovery
Orchestration manages dependencies, schedules, retries, concurrency, and alerts. Monitor freshness, volume, quality, duration, cost, and downstream impact. A failed job should resume or replay without duplication. Version code and schemas, maintain lineage, and test backfills in isolation. Disaster recovery includes raw data, catalogs, permissions, orchestration state, and semantic definitions. ETL is trustworthy when a user can trace a metric to sources and reproduce it after change—not merely when a green pipeline completed.
Worked example: an incremental order pipeline
An ETL job reads database change logs for orders and items, stores immutable events, validates sequence and schema, and merges them into a warehouse fact table at one order-line grain. Event time and update version handle late corrections; deterministic keys make replay idempotent. Dimensions preserve selected customer and product history through surrogate keys. Row counts, order totals, taxes, returns, and cancellations reconcile with source periods.
A breaking source field change stops promotion to trusted tables and alerts owners with downstream lineage. Backfills run with versioned code into isolation and are compared before an atomic swap. Access policy restricts customer identifiers, and deletion propagates to permitted derived copies. Monitoring covers freshness, volume, quality, cost, and dashboard impact. Recovery tests rebuild a period from raw events and restore orchestration state. A green scheduler is insufficient unless business numbers remain reproducible and reconciled.
Implementation evidence and operational readiness
A production decision needs more than a successful demonstration. Define the intended users, operating environment, inputs, outputs, dependencies, owner, and the consequence of each important failure. Establish a reproducible baseline and a versioned evaluation set before tuning. Test ordinary cases, boundary conditions, malformed or missing input, distribution shift, dependency outage, misuse, and the groups or environments most likely to be underserved. Measure task quality together with calibration or uncertainty, latency, throughput, resource cost, accessibility, privacy, and security. Record every transformation and threshold so an independent reviewer can reproduce the result and distinguish evidence from an attractive prototype.
Before launch, assign authority for release, exceptions, changes, rollback, and retirement. Use a staged rollout, preserve a safe fallback, and verify monitoring with deliberately injected failures. Operational telemetry should reveal input quality, output behavior, model or rule version, dependency health, human overrides, and confirmed outcomes without collecting unnecessary sensitive data. Define alert thresholds and a response owner, then review real-world evidence after deployment rather than assuming offline performance will persist. Reevaluate whenever data sources, users, models, vendors, policies, hardware, or objectives change. A maintained system also needs documented recovery, incident learning, deletion and retention procedures, and a clear point at which it should be disabled or replaced.
Frequently asked questions
Is ETL obsolete in cloud data platforms?
No. Some platforms favor ELT, but extraction, transformation and loading responsibilities still exist. Teams often combine both patterns.
What makes an ETL pipeline idempotent?
It can safely process the same input again without creating duplicate or inconsistent destination state, usually through stable keys, checkpoints and transactional writes.
Primary references