AI Fundamentals
What is a Data Fabric?

 Add Unite.AI to your preferred sources on Google
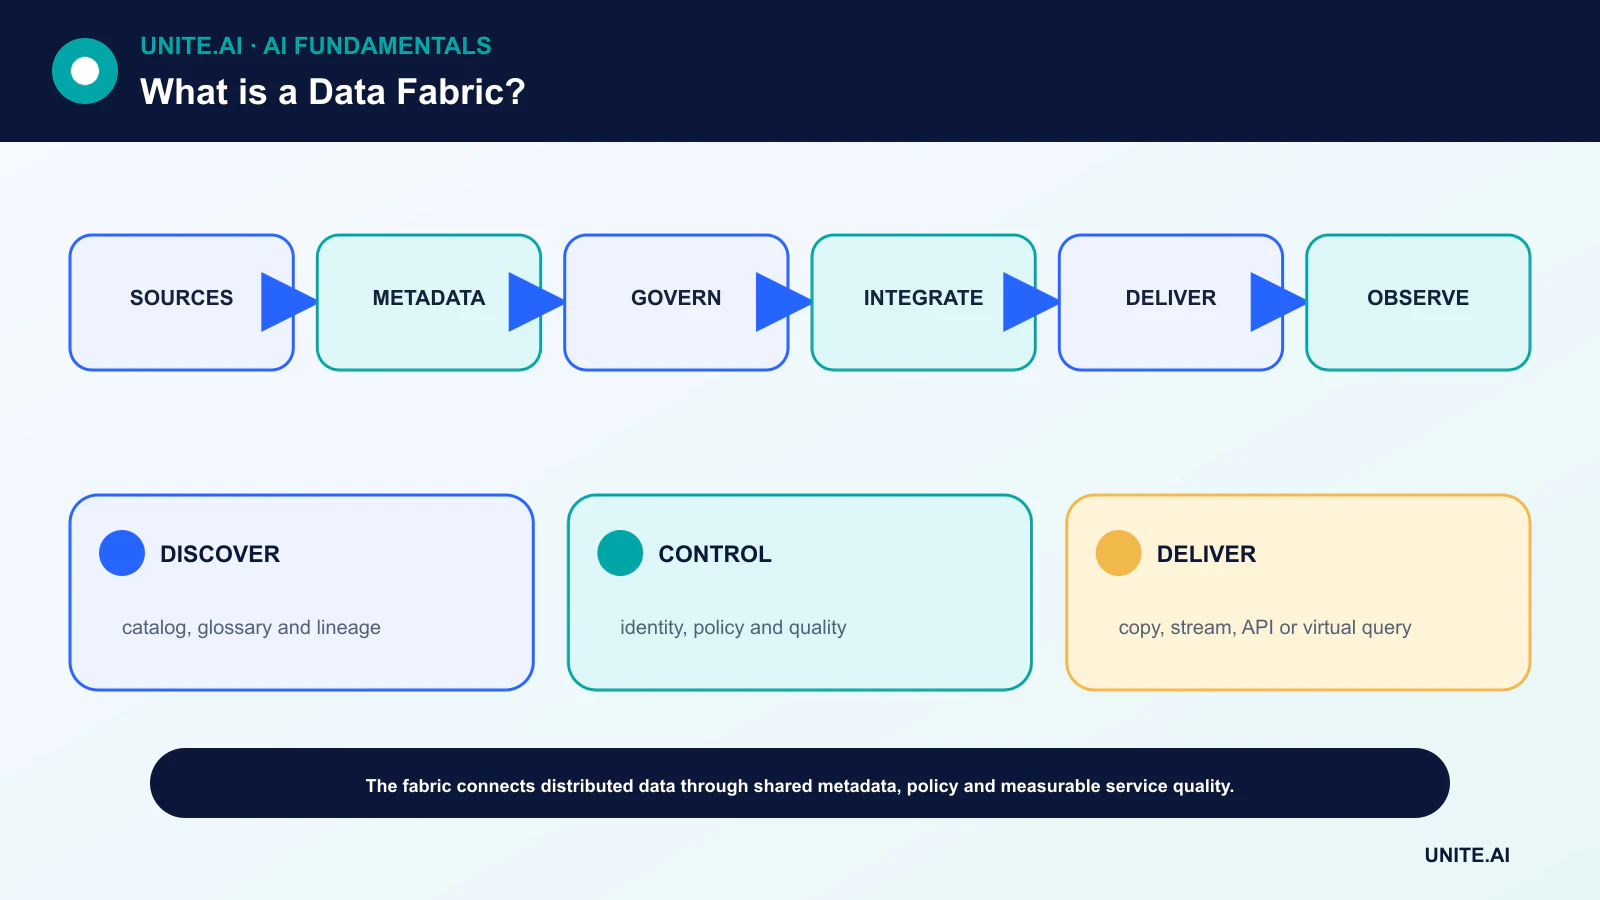
A data fabric is an architectural pattern for discovering, connecting, governing and delivering data across distributed systems. It provides a shared metadata and control layer so people and applications can find trusted data without forcing every dataset into one physical store.
A data fabric is not a single product and it does not erase source-system differences. Its value depends on accurate metadata, clear ownership, enforceable policy, reliable integration and evidence that consumers receive data suited to their purpose.
Key takeaways
- A metadata-rich control plane connects catalogs, lineage, quality, policy and access.
- Data may remain distributed and be copied, streamed, transformed or virtualized according to the workload.
- Data fabric is technology-oriented; data mesh emphasizes domain ownership and data-as-a-product.
- Automation helps scale governance, but accountable owners still define meaning, quality and permissible use.
The control plane and the data plane
The data plane contains databases, files, streams, APIs and the pipelines that move or query them. The control plane records technical and business metadata: schemas, owners, classifications, quality measures, lineage, policies and usage.
A catalog or knowledge graph can connect these facts so a consumer can discover a dataset and understand its context. The fabric then uses metadata to guide access, transformation, observability and policy enforcement across heterogeneous platforms.
Integration without one mandatory store
Some workloads copy data through ETL; others use change-data capture, event streams, APIs or query virtualization. The correct pattern depends on freshness, performance, consistency, sovereignty, cost and source-system limits.
Virtual access can reduce duplication but may expose consumers to source latency and availability. Physical materialization improves performance and reproducibility but creates synchronization and lifecycle responsibilities.
Governance, semantics and quality
A business glossary gives shared meaning to terms such as customer, order or active account. Lineage shows where a field originated and how it changed. Classification and policy determine who can access sensitive records and under what purpose.
Quality rules should be attached to specific use cases. Completeness that is sufficient for a dashboard may be unsafe for automated decisions. A fabric should surface freshness, validation history and known limitations rather than merely labeling an asset certified.
Data fabric, mesh and lakehouse
Data mesh is a sociotechnical approach that assigns domain teams responsibility for interoperable data products. A data fabric emphasizes shared technical services and metadata automation. Organizations can combine them: domain ownership can operate through a common fabric.
A lakehouse combines data-lake flexibility with warehouse-style management and query features. It may be one participating platform, but it is not the entire cross-system fabric. Likewise, a warehouse or catalog alone does not provide all integration and policy functions.
Implementation and evaluation
Begin with a valuable cross-system use case and inventory the minimum sources, owners, policies and service-level expectations. Establish identity, metadata standards, contracts, testing and observability before adding automated recommendations.
Measure discovery time, access-approval time, incident rates, data freshness, reuse and consumer trust. Link the fabric to structured and unstructured data governance and cybersecurity; connectivity without control can increase exposure.
Data-fabric architecture and metadata plane
A data fabric is an architectural approach for connecting distributed data through shared metadata, governance, integration, and access services. It is not one database or product. Sources may remain in warehouses, lakes, operational systems, streams, and SaaS platforms while catalogs describe datasets, lineage traces transformations, policies control access, and semantic definitions make concepts reusable. Virtualization, replication, APIs, and pipelines are complementary delivery methods chosen by latency, scale, source capability, and consistency needs.
Active metadata captures schemas, ownership, usage, quality, classifications, lineage, query patterns, and operational events and can drive automation. A knowledge graph can connect business concepts to physical fields and policies. Automation may recommend joins, detect drift, propagate classifications, or route incidents, but inferred metadata needs confidence and stewardship. A catalog that is not connected to delivery and controls becomes documentation debt; automated integration without semantic ownership creates faster inconsistency.
Integration, governance, and data products
Batch ETL, change-data capture, streams, federation, and reverse ETL have different freshness and failure semantics. Define authoritative sources, identifiers, contracts, event time, late data, deletion, and reconciliation. Virtual queries avoid copies but depend on source performance and availability; materialization improves speed but creates freshness and retention obligations. Sensitive policy must follow or be reevaluated for derived data, caches, embeddings, and exports.
Treat high-value datasets as products with owners, users, documentation, service expectations, tests, and support. Federated ownership lets domains manage meaning while shared standards preserve interoperability. Central teams provide platform capabilities and governance, not ownership of every field. Measure discovery time, reuse, data quality, access lead time, incident resolution, trusted metric adoption, and cost. The number of catalog entries or connectors is not evidence that people can find and use reliable data.
Implementation strategy
Start with one cross-domain journey whose delays and risks are known. Inventory sources and contracts, establish identity and classification, connect lineage and quality, then automate repeated controls. Avoid a multi-year attempt to model the entire enterprise before delivering value. Test source outage, schema change, revoked access, late events, and disaster recovery. A data fabric succeeds when distributed data becomes easier to govern and use without erasing the operational realities and accountability of the systems where it originates.
Worked example: a customer-data fabric
A company connects commerce, support, marketing, and product data while leaving operational systems authoritative. A shared catalog links customer, account, order, consent, and interaction definitions to physical fields. Change-data capture feeds governed products, while virtualization serves low-volume current lookups and materialized tables support analytics. Identity, lineage, quality, and policy are implemented before an AI personalization layer is allowed to use the data.
A consent withdrawal propagates through warehouse tables, search indexes, embeddings, and activation systems, with evidence of completion. Schema contracts and reconciliation tests detect source changes. Owners publish freshness and quality expectations, and usage metadata helps retire unused copies. The pilot measures access lead time, trusted metric reuse, incident resolution, and privacy compliance. The fabric is considered successful because one cross-domain journey becomes reliable and governable—not because a vendor connected the largest number of sources.
Implementation evidence and operational readiness
A production decision needs more than a successful demonstration. Define the intended users, operating environment, inputs, outputs, dependencies, owner, and the consequence of each important failure. Establish a reproducible baseline and a versioned evaluation set before tuning. Test ordinary cases, boundary conditions, malformed or missing input, distribution shift, dependency outage, misuse, and the groups or environments most likely to be underserved. Measure task quality together with calibration or uncertainty, latency, throughput, resource cost, accessibility, privacy, and security. Record every transformation and threshold so an independent reviewer can reproduce the result and distinguish evidence from an attractive prototype.
Before launch, assign authority for release, exceptions, changes, rollback, and retirement. Use a staged rollout, preserve a safe fallback, and verify monitoring with deliberately injected failures. Operational telemetry should reveal input quality, output behavior, model or rule version, dependency health, human overrides, and confirmed outcomes without collecting unnecessary sensitive data. Define alert thresholds and a response owner, then review real-world evidence after deployment rather than assuming offline performance will persist. Reevaluate whenever data sources, users, models, vendors, policies, hardware, or objectives change. A maintained system also needs documented recovery, incident learning, deletion and retention procedures, and a clear point at which it should be disabled or replaced.
Frequently asked questions
Does a data fabric move all data into one place?
No. It can coordinate data that remains distributed and choose physical movement or virtualization per workload.
Is a data fabric the same as a data mesh?
No. Fabric primarily describes enabling architecture and automation; mesh primarily describes decentralized domain ownership and data-product responsibilities. They can coexist.
Primary references