AI Fundamentals
What is Gradient Boosting?

 Add Unite.AI to your preferred sources on Google
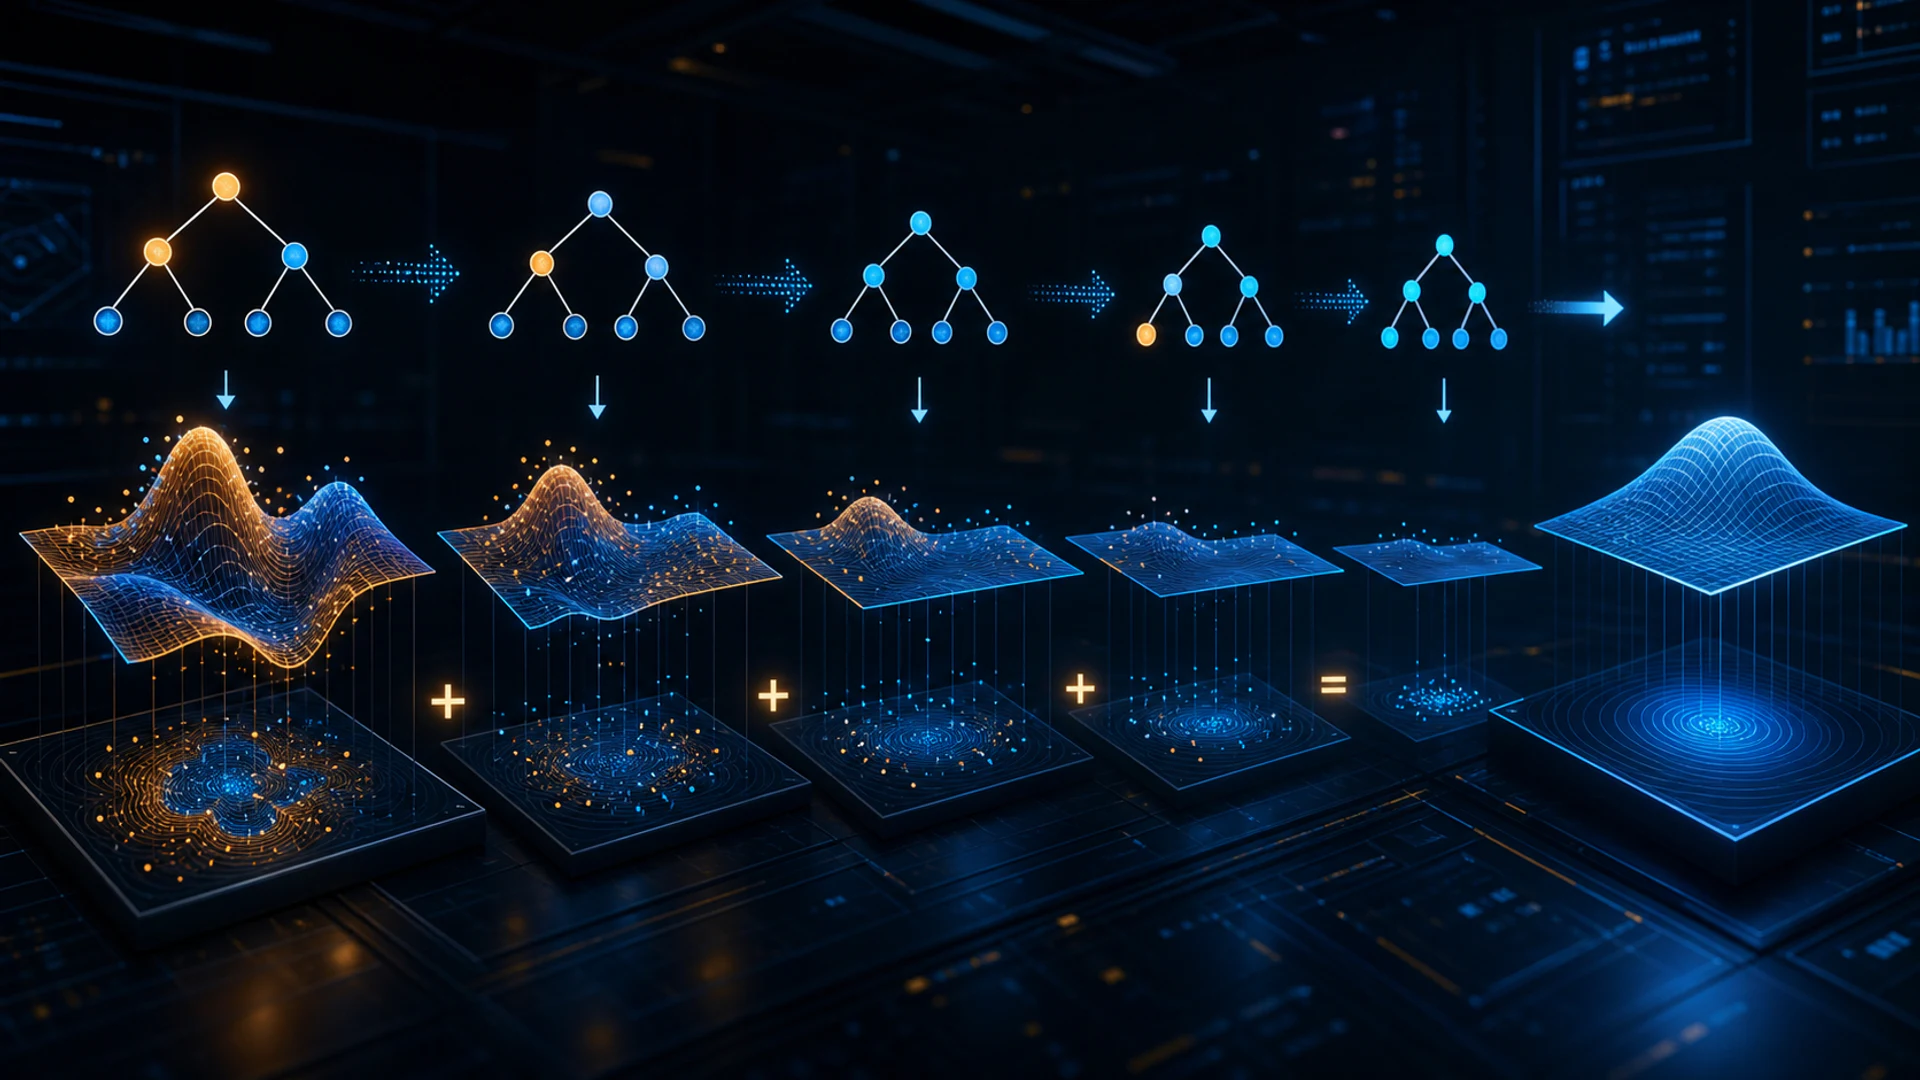
Gradient boosting builds an additive prediction model in stages. Each new weak learner—most often a shallow decision tree—is trained to reduce the errors of the current ensemble by approximating the negative gradient of a chosen loss.
The final prediction is the sum of many small corrections. This can model nonlinear relationships and interactions in tabular data, but careful validation is required because the same flexibility can fit noise and leakage.
Key takeaways
- Gradient boosting is functional gradient descent: each learner moves the ensemble toward lower loss.
- Learning rate and number of trees trade step size against model length.
- Tree depth controls interaction complexity; subsampling and regularization can reduce overfitting.
- XGBoost, LightGBM and CatBoost are related implementations with different engineering and categorical-feature choices.
Sequential error correction
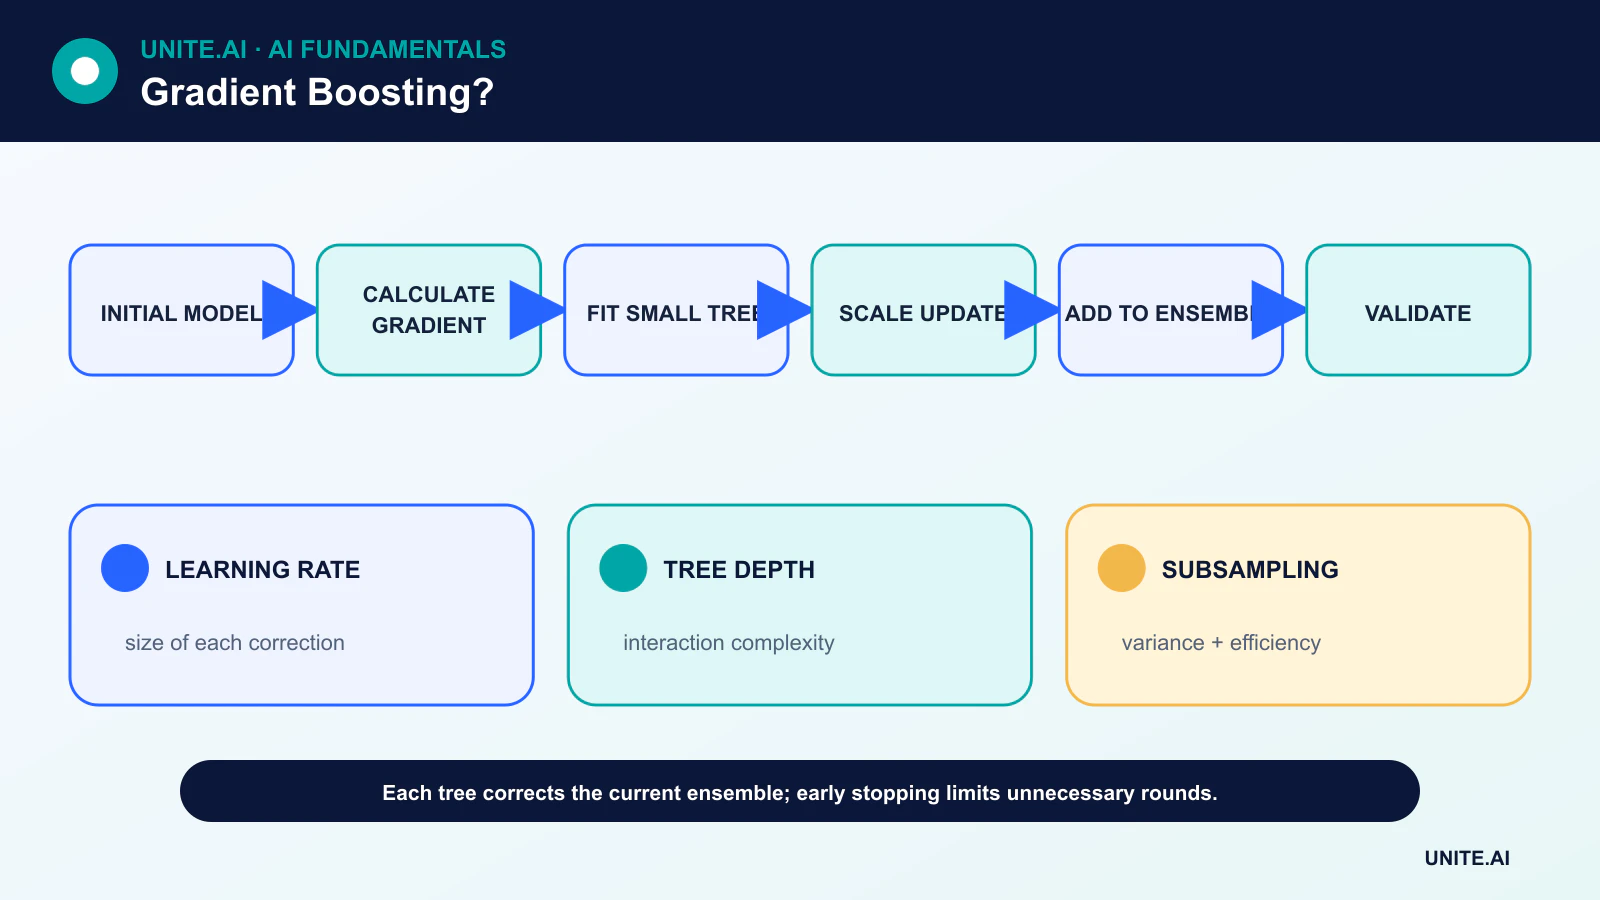
Start with a simple constant prediction. Compute how the loss would change for each training example, then fit a decision tree to those negative gradients. Add a scaled version of the tree to the ensemble and repeat.
For squared-error regression, the negative gradients are residuals, which makes the process intuitive. Other differentiable losses produce different pseudo-residuals for classification, robust regression or ranking.
Learning rate, tree depth and rounds
A smaller learning rate makes each tree a gentler correction and usually requires more rounds. Shallow trees limit interaction order; deeper trees capture more complex patterns but increase variance and cost.
There is no best setting independent of data. Tune jointly with time-aware or grouped validation where necessary, and use early stopping on a validation set that reflects deployment.
Regularization and subsampling
Row subsampling introduces stochasticity and can reduce variance. Column subsampling limits repeated reliance on the same features. L1/L2 penalties, minimum leaf size, split-gain thresholds and maximum depth constrain individual trees.
Regularization does not fix target leakage or a nonrepresentative split. Overfitting controls must begin with the data pipeline.
XGBoost, LightGBM and CatBoost
XGBoost introduced a scalable regularized tree-boosting system with sparsity-aware algorithms. LightGBM uses histogram techniques and leaf-wise growth for efficiency. CatBoost includes ordered techniques designed to reduce target leakage when handling categorical features.
Library defaults and category handling differ. Benchmarks should include preprocessing time, memory, prediction latency and native missing-value behavior rather than only training speed.
Evaluation and interpretation
Use task-appropriate held-out metrics, probability calibration for risk decisions and subgroup checks. Feature importance based on split counts or gain can be biased and does not establish causality.
Partial dependence, accumulated local effects and SHAP-style attributions can help inspect behavior, but correlated features complicate interpretation. A simpler linear or monotonic model may be preferable when policy or explanation constraints dominate.
Sequential trees and residual correction
Gradient boosting builds an additive model one weak learner at a time. Each new tree approximates the negative gradient of the chosen loss with respect to current predictions—residuals for squared-error regression and a transformed error signal for classification. The learning rate scales each tree’s contribution, while tree depth controls interactions. Many shallow trees can capture complex nonlinear relationships. Unlike bagging, trees are dependent and sequential, which improves fit but makes the method sensitive to noise, leakage, and tuning.
Implementations such as gradient-boosted decision trees use shrinkage, row and feature subsampling, histogram splits, regularization, and efficient missing-value handling. XGBoost uses second-order information and explicit penalties; LightGBM grows leaves and uses histogram and sampling techniques; CatBoost handles categorical variables with ordered statistics designed to reduce target leakage. Their defaults and category treatment differ. Preprocessing and hyperparameter searches must occur inside the training fold, especially when target encoding is involved.
Tuning, interpretation, and evaluation
Key controls include number of trees, learning rate, maximum depth or leaves, minimum leaf data, row and column sampling, and regularization. Lower learning rates usually need more trees. Use early stopping on a validation set and then confirm on an untouched test set. Evaluate class-specific metrics, calibration, error cost, and performance by time and subgroup. Tree boosting can dominate tabular benchmarks but still lose to a linear baseline when relationships are simple or data is unstable.
Gain-based feature importance can favor variables with many split opportunities. Use permutation importance and SHAP cautiously, inspect correlated features, and perform counterfactual or ablation tests. Explanations describe the fitted model, not causal effects. Partial dependence can evaluate impossible feature combinations when predictors are correlated. Check whether missingness or identifiers are shortcuts and whether monotonic constraints are justified by domain rules.
Production operation
Serialize the full feature pipeline, category mapping, model, and threshold. Validate predictions across library or compiler versions and measure latency at realistic tree count and batch size. Monitor schema, missingness, category drift, score distribution, calibration, and outcomes. New categories and changed source systems can route examples through unintended branches. Keep rollback and retraining evidence. Gradient boosting is powerful for structured data, but its accuracy depends on stable feature meaning, leakage-free validation, and operational controls around a complex ensemble.
Worked example: gradient boosting for claim triage
An insurer uses boosted trees to prioritize claims for specialist review, not to deny payment. Features are limited to information available at intake, categorical encoding is fitted within folds, and claims are split by customer and time. A regularized logistic baseline and several boosting libraries are compared. Evaluation reports recall at reviewer capacity, calibration, false burden, processing time, and errors across claim types and relevant affected groups.
Explanations display source fields and uncertainty but are not described as causal reasons for fraud. Low-support categories and missing schema route to ordinary review. The full feature pipeline, model, and threshold are versioned; monitoring tracks missingness, new categories, score drift, overrides, and outcomes. A policy or source-system change requires reevaluation. The model is removed if it merely shifts workload or creates unequal scrutiny without verified operational benefit.
Implementation evidence and operational readiness
A production decision needs more than a successful demonstration. Define the intended users, operating environment, inputs, outputs, dependencies, owner, and the consequence of each important failure. Establish a reproducible baseline and a versioned evaluation set before tuning. Test ordinary cases, boundary conditions, malformed or missing input, distribution shift, dependency outage, misuse, and the groups or environments most likely to be underserved. Measure task quality together with calibration or uncertainty, latency, throughput, resource cost, accessibility, privacy, and security. Record every transformation and threshold so an independent reviewer can reproduce the result and distinguish evidence from an attractive prototype.
Before launch, assign authority for release, exceptions, changes, rollback, and retirement. Use a staged rollout, preserve a safe fallback, and verify monitoring with deliberately injected failures. Operational telemetry should reveal input quality, output behavior, model or rule version, dependency health, human overrides, and confirmed outcomes without collecting unnecessary sensitive data. Define alert thresholds and a response owner, then review real-world evidence after deployment rather than assuming offline performance will persist. Reevaluate whenever data sources, users, models, vendors, policies, hardware, or objectives change. A maintained system also needs documented recovery, incident learning, deletion and retention procedures, and a clear point at which it should be disabled or replaced.
Frequently asked questions
Is gradient boosting the same as gradient descent?
It uses the gradient-descent idea in function space, adding learners that reduce loss. The base learner is often a tree rather than a parameter vector updated directly.
Why use many shallow trees?
Each tree makes a limited correction. Their sum can express complex functions while depth and learning rate control how aggressively the model fits interactions.
Primary references