
AI Fundamentals
What Is Incident Automation? Workflows, Guardrails, and Use Cases

 Add Unite.AI to your preferred sources on Google
Incident automation uses software to detect, enrich, route, coordinate, and sometimes remediate operational or security incidents. It connects monitoring signals with runbooks, ticketing, communication, access controls, and recovery actions so responders spend less time copying data and more time making decisions.
Automation is not the removal of human accountability. A safe program distinguishes low-risk deterministic steps from actions that can affect customers or production, then applies approvals, scoped credentials, audit trails, timeouts, and rollback according to impact.
Key takeaways
- Automate repeatable evidence gathering before attempting autonomous remediation.
- Use severity, confidence, blast radius, and reversibility to select an approval level.
- Treat every runbook as versioned production code with tests and an owner.
- Measure detection, acknowledgement, recovery, recurrence, and user impact—not alert volume alone.
From signal to coordinated response
A workflow may deduplicate alerts, attach recent deploys and logs, identify the service owner, open an incident record, page the on-call team, create a communication channel, and start a timeline. These steps reduce cognitive load without making a risky diagnosis automatically.
Correlation must preserve evidence. If a platform groups symptoms too aggressively, it can hide concurrent incidents. Link the automation to IT operations ownership and retain the raw signals responders may need.
Choose actions by risk
Read-only queries, snapshots, and reversible traffic shifts are generally easier to automate than deleting data, rotating broad credentials, or changing a production schema. Define preconditions, an execution timeout, postconditions, and a rollback for every action.
Use least-privilege service identities and separate authorization from the workflow engine. High-impact steps should require an identified approver. If AIOps proposes a cause or fix, responders still need supporting evidence and a safe way to reject it.
Build reliable runbooks
A runbook should declare inputs, dependencies, owner, scope, failure behavior, and evidence produced. Test it in staging and through game days. Idempotent steps are valuable because retrying them does not create additional harm.
Version and review automation like other software. Monitor credential expiry, API changes, rate limits, partial execution, and hidden coupling between services. Manual procedures remain necessary when the automation platform itself is unavailable.
Learn after recovery
Automation should preserve a time-stamped record of signals, decisions, actions, approvals, and outcomes. A blameless review can then separate contributing system conditions from the final trigger and turn lessons into tested improvements.
Useful measures include mean time to acknowledge and restore, percentage of safe steps automated, failed-action rate, repeat incidents, and customer impact. Connect findings to DevOps planning instead of optimizing for the number of closed tickets.
Types of incident automation
Event automation normalizes and enriches incoming signals. Coordination automation creates an incident record, pages owners, opens communication channels, and posts status updates. Diagnostic automation runs read-only queries or captures snapshots. Remediation automation changes system state, while recovery automation verifies service health and closes temporary mitigations.
These categories should not share one default trust level. Enrichment can often run automatically; a production failover may require confidence checks and an approver; data restoration usually needs an incident commander and application owner. The control should follow potential impact, not whether the step is implemented by a rule or a machine-learning model.
Security incidents add evidence-preservation requirements. Automation must avoid modifying a compromised host before volatile data is captured, exposing sensitive indicators in public channels, or quarantining shared infrastructure without understanding the blast radius. Operational and forensic runbooks can overlap, but their ordering may differ.
Workflow design and control plane
Model the runbook as explicit states with preconditions and terminal outcomes. Every action should report started, succeeded, failed, timed out, or skipped, along with an immutable execution identifier. A central orchestrator can coordinate steps, but downstream services should enforce their own authorization and validate inputs independently.
Use scoped, short-lived credentials and restrict network paths from the automation engine. Separate development, testing, and production runners. Secrets must not appear in chat transcripts or logs. For high-impact actions, require two-person approval or a break-glass role whose use creates an immediate review trail.
Design for partial failure. A ticket may be created while paging fails; a traffic shift may succeed in one region and time out in another. Compensating actions, reconciliation jobs, and clear ownership prevent the workflow from reporting success merely because the orchestration process ended.
Examples, testing, and maturity
A mature first use case is database connection exhaustion: collect pool metrics, recent deploys, slow queries, and owner information; open an incident; propose a reversible scaling or traffic action; require approval; then verify error rate and latency. The same pattern can serve certificate expiry, disk pressure, failed jobs, or suspicious account activity.
Test runbooks through unit tests, mocked APIs, staging incidents, game days, and controlled production drills. Inject stale data, permission denial, slow dependencies, duplicate events, and conflicting incidents. Confirm that retries are safe and that responders can take manual control without fighting the automation.
Maturity progresses from notification, to enrichment, to guided actions, to bounded auto-remediation. Advancement should depend on evidence: stable diagnosis, low failed-action rates, verified rollback, and clear user benefit. Autonomous closure should be rare until the system can prove recovery and preserve enough evidence for later learning.
Worked example: automating a production service incident
Consider a payment API whose error rate rises after a deployment. Monitoring emits a structured alert containing service, environment, region, version, error budget, and runbook link. Automation enriches it with the change record, dependency health, recent logs, and ownership, then groups duplicate alerts into one incident. A deterministic policy can pause further rollout immediately; a rollback should require evidence that the new version is causal and that rollback is safe.
The workflow assigns an incident commander, opens communication channels, records a timeline, and suggests diagnostic steps. Automated remediation starts with low-risk reversible actions such as shifting traffic to a healthy instance. Every action needs authorization, concurrency limits, a timeout, verified postconditions, and rollback. Generative summaries may assist responders, but source telemetry and commands remain visible so the team can challenge an incorrect narrative.
Measure time to detect, acknowledge, mitigate, and recover; alert volume; duplicate suppression; remediation success; recurrence; and automation-caused harm. Run game days for expired credentials, partial regions, misleading alerts, and failed rollbacks. After recovery, preserve the factual timeline, identify contributing technical and organizational conditions, update runbooks and tests, and track corrective work to completion rather than treating a fast mitigation as the end of reliability work.
Practical implementation checklist
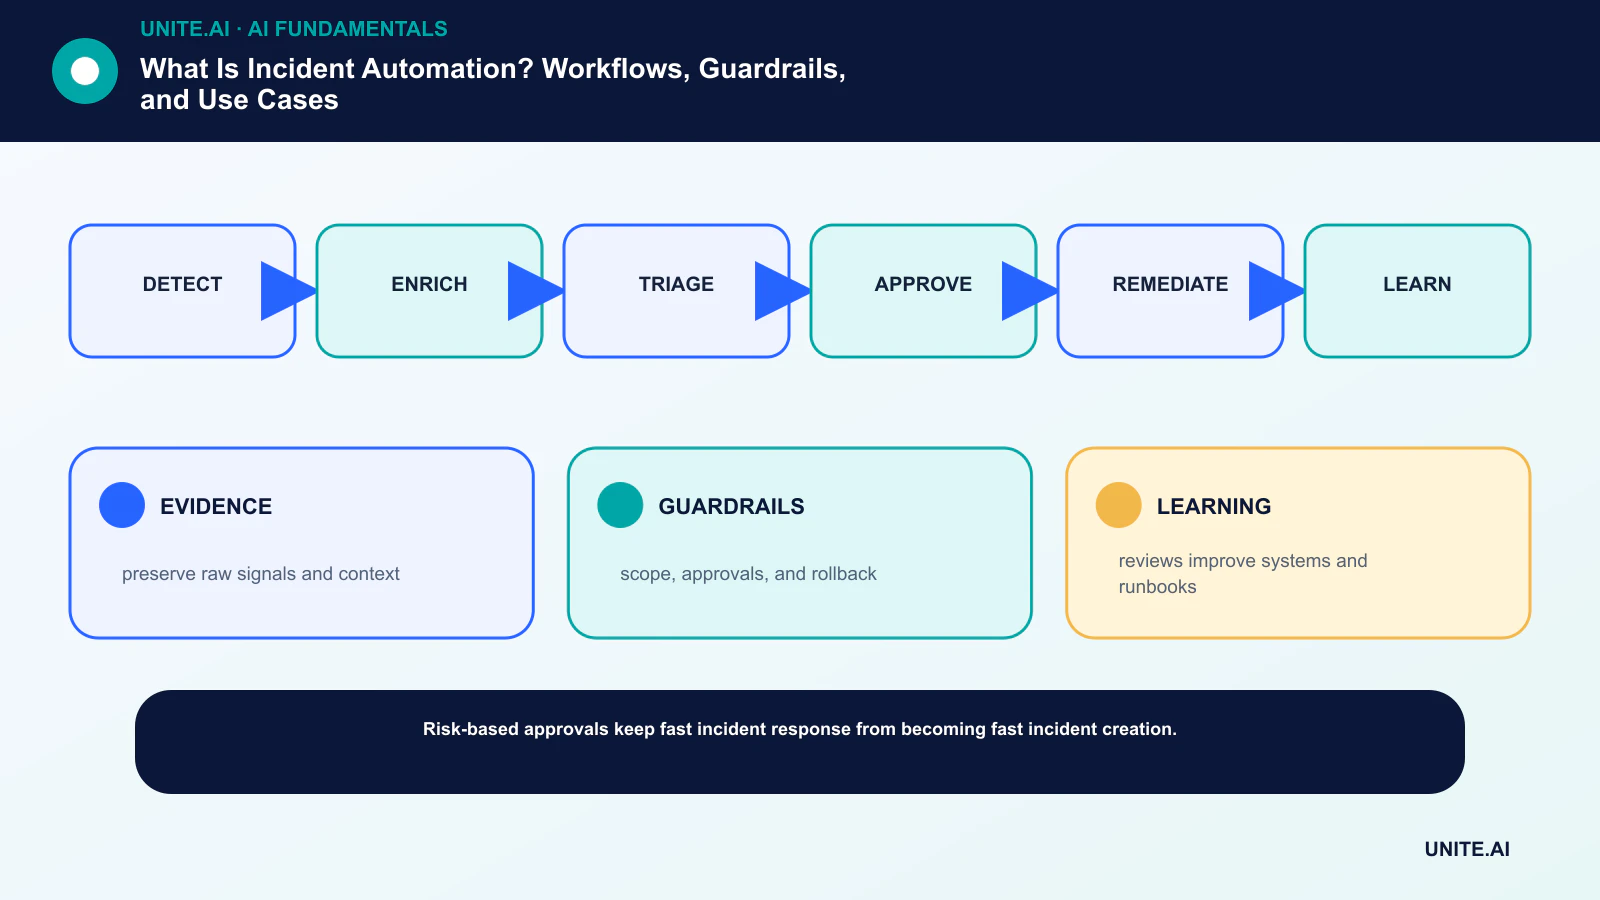
Turn the concept into a bounded, testable workflow: detect → enrich → triage → approve → remediate → learn. Name an accountable owner, document the data and dependencies, establish a simple baseline, set acceptance and stop criteria, test representative failures, and define monitoring, rollback, and review before expanding scope. Record versions and assumptions so another team can reproduce the result and understand what changed.
Before launch, run a documented readiness review with the people who build, operate, secure, and are affected by the system. Test normal cases, boundary conditions, dependency failures, and misuse; preserve the evidence and unresolved risks. Define who can approve release, change a threshold, override an output, or stop operation. Revisit the decision after real-world data arrives, because a technically successful pilot does not guarantee reliable performance at broader scale.
- EVIDENCE: preserve raw signals and context.
- GUARDRAILS: scope, approvals, and rollback.
- LEARNING: reviews improve systems and runbooks.
Frequently asked questions
Is incident automation the same as AIOps?
No. AIOps applies analytics or machine learning to operations data. Incident automation is the broader execution and coordination layer; it can use simple rules, AIOps outputs, or both.
What should be automated first?
Start with high-frequency, low-risk, well-understood steps such as enrichment, ownership lookup, evidence capture, status updates, and reversible diagnostics.
Primary references











