AI Fundamentals
What Is Asset Performance Management (APM)?

 Add Unite.AI to your preferred sources on Google
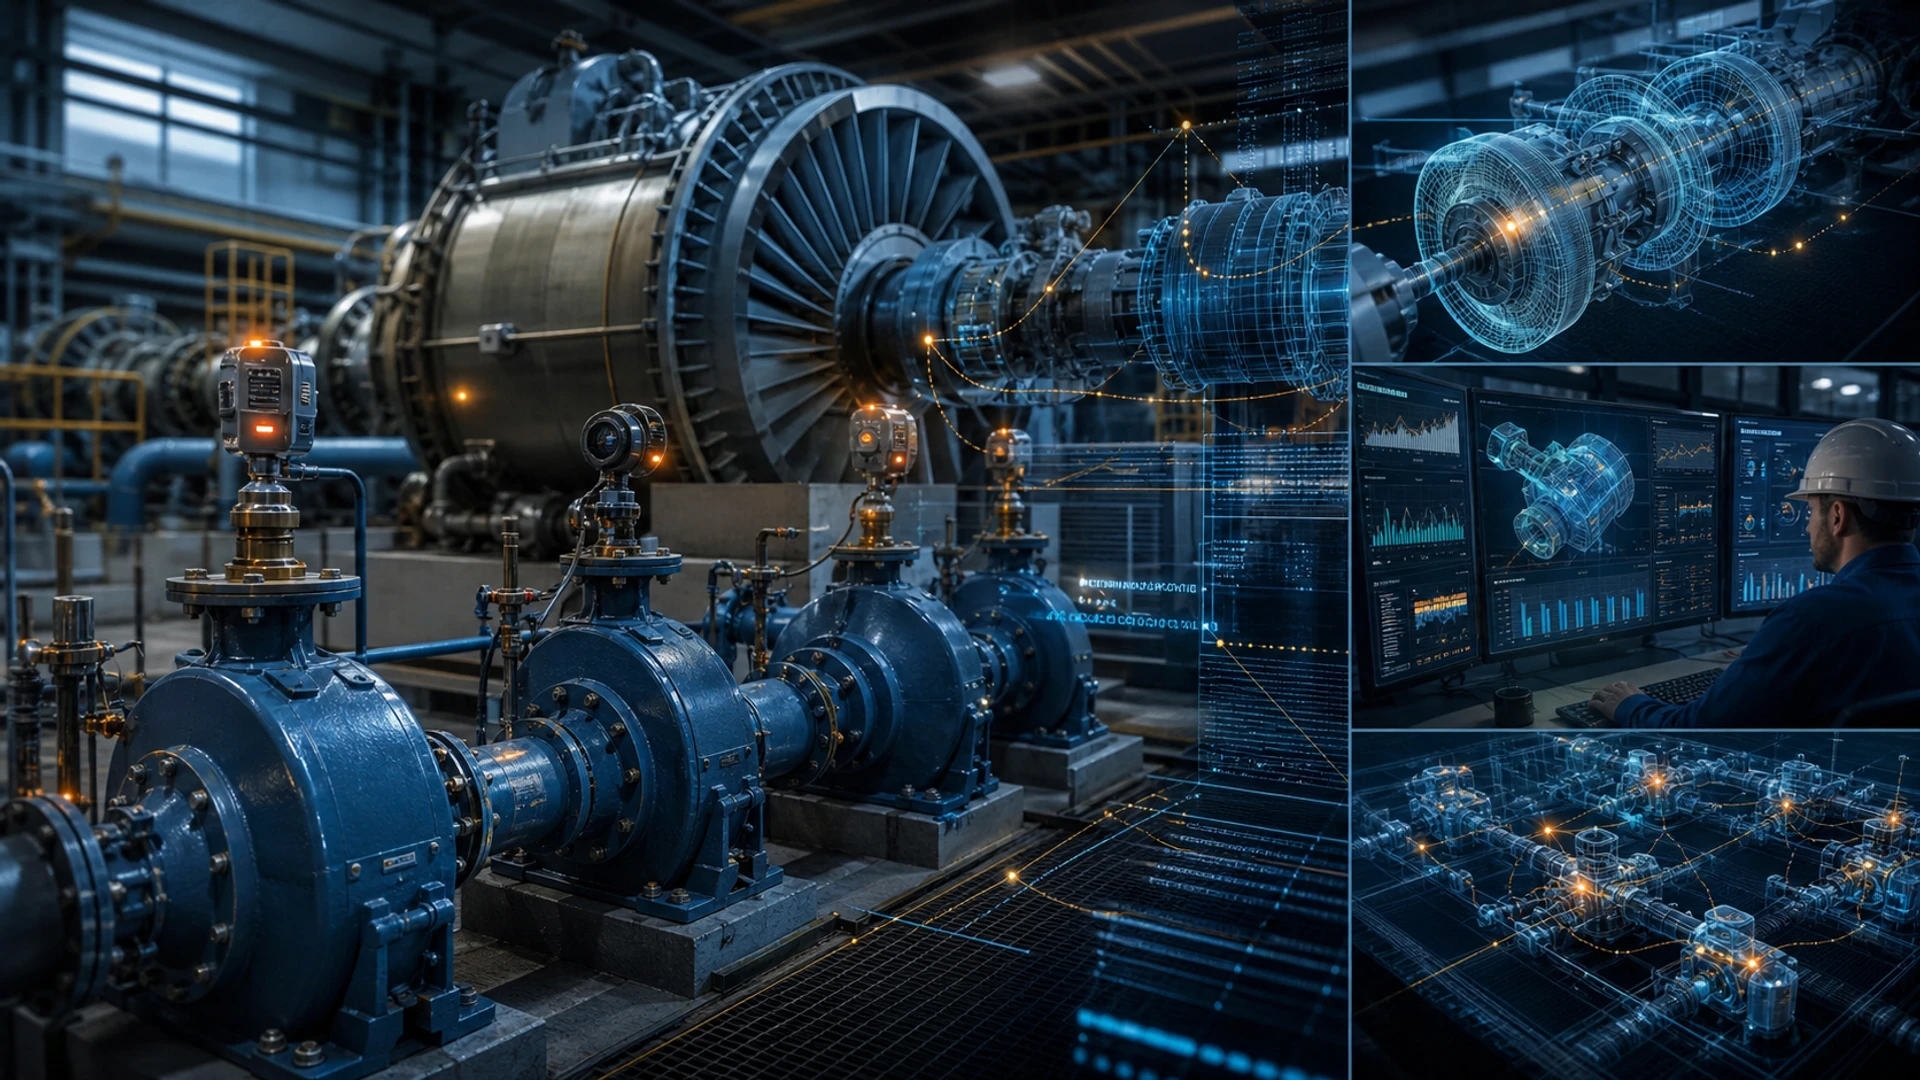
Asset performance management (APM) combines asset strategy, maintenance, condition monitoring, reliability analysis, and operational data to improve the value delivered by physical assets. It is commonly used for equipment such as turbines, pumps, vehicles, production lines, and infrastructure.
APM is not a sensor dashboard or a predictive-maintenance model by itself. It is a decision process that balances performance, cost, risk, safety, and sustainability across the asset lifecycle, with clear ownership for inspections, work, spares, and capital planning.
Key takeaways
- Begin with criticality and failure consequences, not with the easiest sensor to collect.
- Combine condition data with maintenance history, operating context, and engineering knowledge.
- Use predictive signals to support a defined work decision and lead-time requirement.
- Measure avoided risk, availability, maintenance quality, lifecycle cost, and false alarms.
From asset strategy to work
Organizations define objectives, asset hierarchies, criticality, performance standards, failure modes, and maintenance strategies. A work-management system schedules inspections and repairs; APM analytics help prioritize when and why work should occur.
The same condition can imply different action for a redundant low-cost pump and a safety-critical turbine. APM connects technical evidence to business and safety context rather than optimizing one prediction score.
Data and digital representations
Useful sources include sensor time series, alarms, operator rounds, maintenance notes, parts, environment, loads, and design limits. Asset identifiers and timestamps must align before analysis. Missing, drifting, or replaced sensors can create false trends.
A digital twin may combine engineering models and live state, but it needs validated assumptions and update rules. Unstructured technician notes can add context that telemetry lacks.
Condition, prediction, and decision
Thresholds detect known limits; anomaly models flag deviations; diagnostic models estimate causes; prognostic models estimate remaining useful life. Each requires a time horizon and uncertainty appropriate to the maintenance decision.
A model that predicts failure five minutes before it occurs may be accurate but operationally useless if parts require a week. Machine learning should be compared with rules and reliability methods and tested across operating regimes.
Implementation and measurement
Start with a critical asset class, a credible failure mode, available lead time, and an owner who can act. Integrate recommendations into planning, work orders, and inventory; collect the outcome so the rule or model can be reviewed.
Track availability, unplanned downtime, maintenance cost, schedule compliance, false alarms, missed events, safety exposure, and lifecycle value. Avoid claiming avoided failures without a counterfactual method and documented assumptions.
Asset hierarchy, failure behavior, and criticality
An APM program begins with an asset hierarchy that connects sites, systems, equipment, assemblies, and maintainable components. Each level needs consistent identifiers, ownership, location, specifications, and relationships. Without that foundation, sensor streams, work orders, inspection findings, and cost records cannot reliably describe the same physical asset.
Failure modes explain how an asset can stop meeting its required function, why the failure happens, what evidence appears first, and what consequence follows. Failure mode and effects analysis, reliability-centered maintenance, and root-cause analysis turn maintenance from a calendar activity into a risk-informed discipline. The analysis should distinguish symptoms from causal mechanisms.
Criticality combines probability with consequences for safety, environment, production, quality, compliance, and cost. A redundant pump serving a nonessential loop should not receive the same monitoring budget as a single-point-of-failure compressor. Criticality changes with operating context, so teams should revisit rankings after process, asset, or demand changes.
Condition monitoring, prediction, and maintenance decisions
Condition monitoring can use vibration, temperature, pressure, current, acoustic emission, lubricant analysis, visual inspection, and operator observations. Sampling frequency must match the physics of the failure. High-frequency bearing vibration and slowly drifting corrosion require different sensors, storage, features, and alert logic. Calibration and installation quality are part of data quality.
Predictive models may detect anomalies, classify known faults, estimate health indicators, or predict remaining useful life. A statistically unusual signal is not automatically an actionable failure. Models need operating-state context, uncertainty, lead-time evaluation, and validation across equipment, seasons, loads, and maintenance events. False alarms consume trust and labor; missed detections can create severe loss.
The output of analytics must connect to a decision: inspect, lubricate, derate, schedule work, order a part, or shut down. Decision thresholds should reflect failure consequence, intervention lead time, workforce capacity, spares, and production windows. The economically optimal threshold is rarely the threshold that maximizes a generic model metric.
APM integration, value measurement, and governance
APM connects operational technology with enterprise systems such as computerized maintenance management, enterprise asset management, historians, inventory, and planning. Integration should preserve timestamps, units, asset identity, work status, and provenance. Network segmentation and controlled gateways are essential because diagnostic convenience must not create a path into safety-critical control systems.
Measure value through avoided downtime, reduced emergency work, maintenance cost, spare-parts availability, energy efficiency, yield, safety exposure, and asset life. Avoided failures are counterfactual, so use credible baselines, comparable assets, documented assumptions, and sensitivity ranges. A pilot that finds many anomalies but changes no maintenance decisions has not demonstrated business value.
Governance assigns owners for sensors, models, alarm rules, failure libraries, and work processes. Review alerts after every intervention, record whether the diagnosis was correct, and feed confirmed outcomes back into rules and models. Operators and maintainers need a way to challenge recommendations; local knowledge is evidence, not resistance to automation.
Worked example: protecting a critical rotating asset
For a production compressor, the team maps components and failure modes, ranks lost-production and safety consequences, and connects historian tags, vibration sensors, lubricant samples, inspections, and work orders to one asset identity. Baseline data must cover startup, steady load, turndown, and seasonal conditions. Otherwise the model may flag normal operating transitions as faults or miss degradation visible only at a particular load.
An analytics layer detects changes in vibration spectrum and bearing temperature, estimates uncertainty, and shows the evidence beside comparable historical events. A persistent alert creates an inspection request rather than automatically shutting down. The maintainer records findings, action, replaced part, and confirmed cause. Those outcomes determine whether the threshold, failure model, or sensor installation should change.
Evaluate warning lead time, confirmed detection rate, false alarm burden, downtime avoided, emergency work, spare-parts readiness, and maintenance cost relative to a documented baseline. Include the cost of sensors, integration, analysis, and changed work processes. Cybersecurity review isolates monitoring from control, and governance assigns owners for data and models. The goal is a safer economic maintenance decision, not the largest possible collection of asset telemetry.
Practical implementation checklist
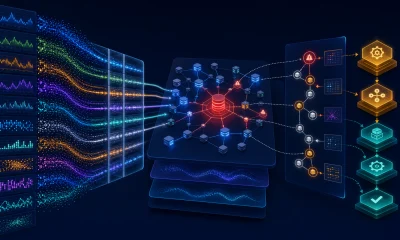
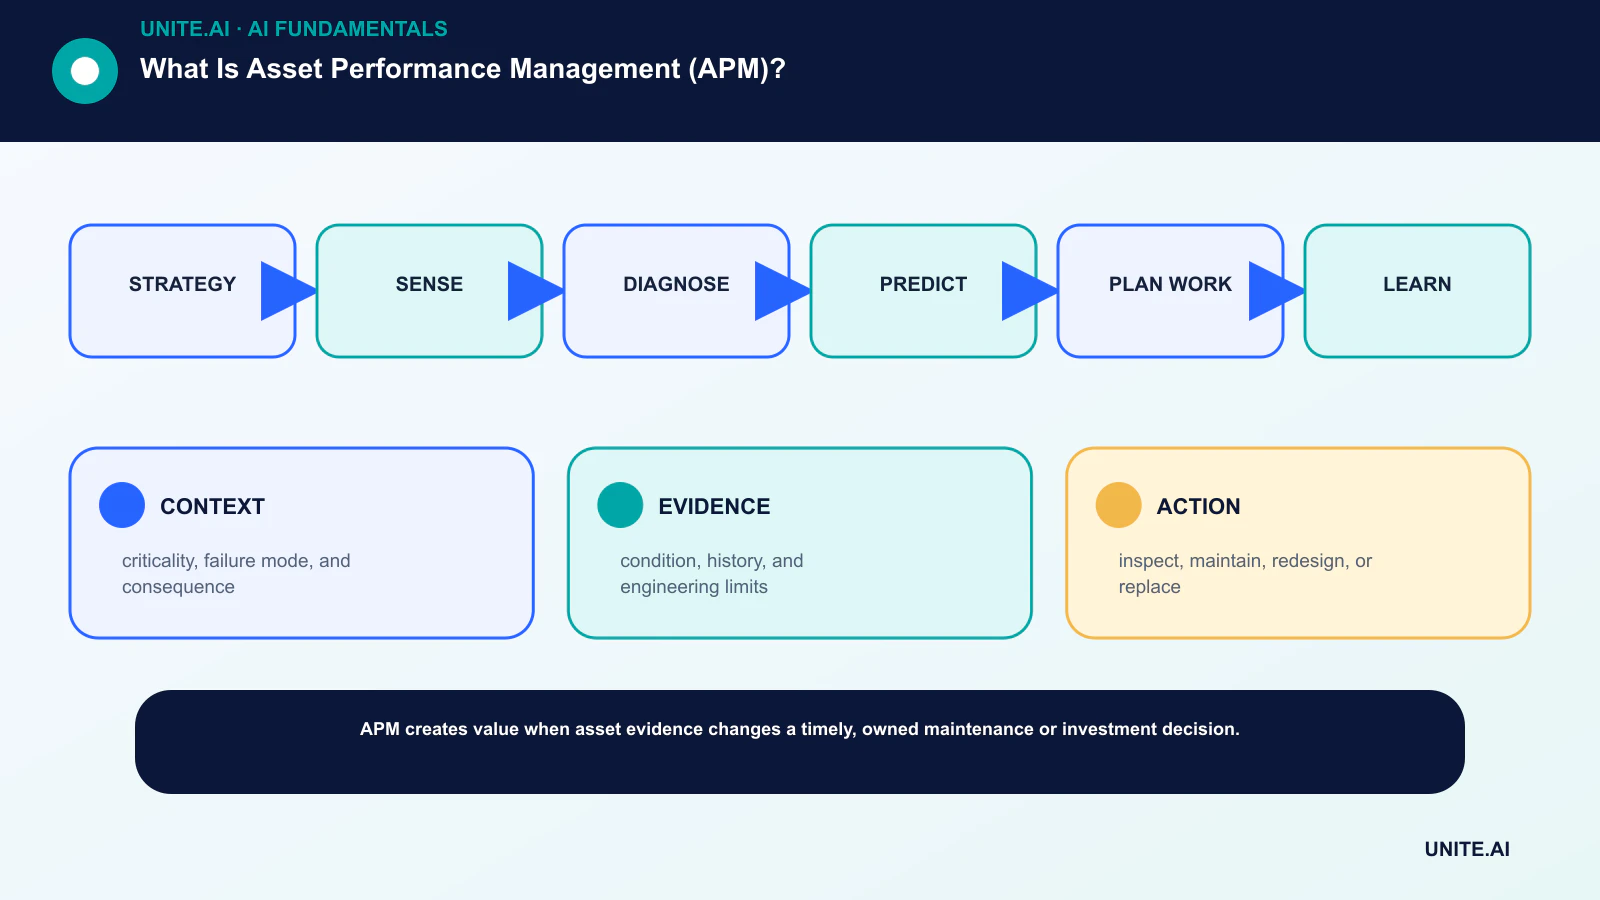
Turn the concept into a bounded, testable workflow: strategy → sense → diagnose → predict → plan work → learn. Name an accountable owner, document the data and dependencies, establish a simple baseline, set acceptance and stop criteria, test representative failures, and define monitoring, rollback, and review before expanding scope. Record versions and assumptions so another team can reproduce the result and understand what changed.
Before launch, run a documented readiness review with the people who build, operate, secure, and are affected by the system. Test normal cases, boundary conditions, dependency failures, and misuse; preserve the evidence and unresolved risks. Define who can approve release, change a threshold, override an output, or stop operation. Revisit the decision after real-world data arrives, because a technically successful pilot does not guarantee reliable performance at broader scale.
- CONTEXT: criticality, failure mode, and consequence.
- EVIDENCE: condition, history, and engineering limits.
- ACTION: inspect, maintain, redesign, or replace.
Frequently asked questions
How is APM different from a CMMS?
A CMMS primarily manages maintenance work, schedules, and records. APM adds asset strategy, reliability and condition analysis, prioritization, and performance decisions; the systems often integrate.
Is predictive maintenance required for APM?
No. Preventive, condition-based, run-to-failure, redesign, and replacement strategies can all be appropriate. Prediction is one tool within an asset strategy.
Primary references