AI Fundamentals
What is Computer Vision?

 Add Unite.AI to your preferred sources on Google
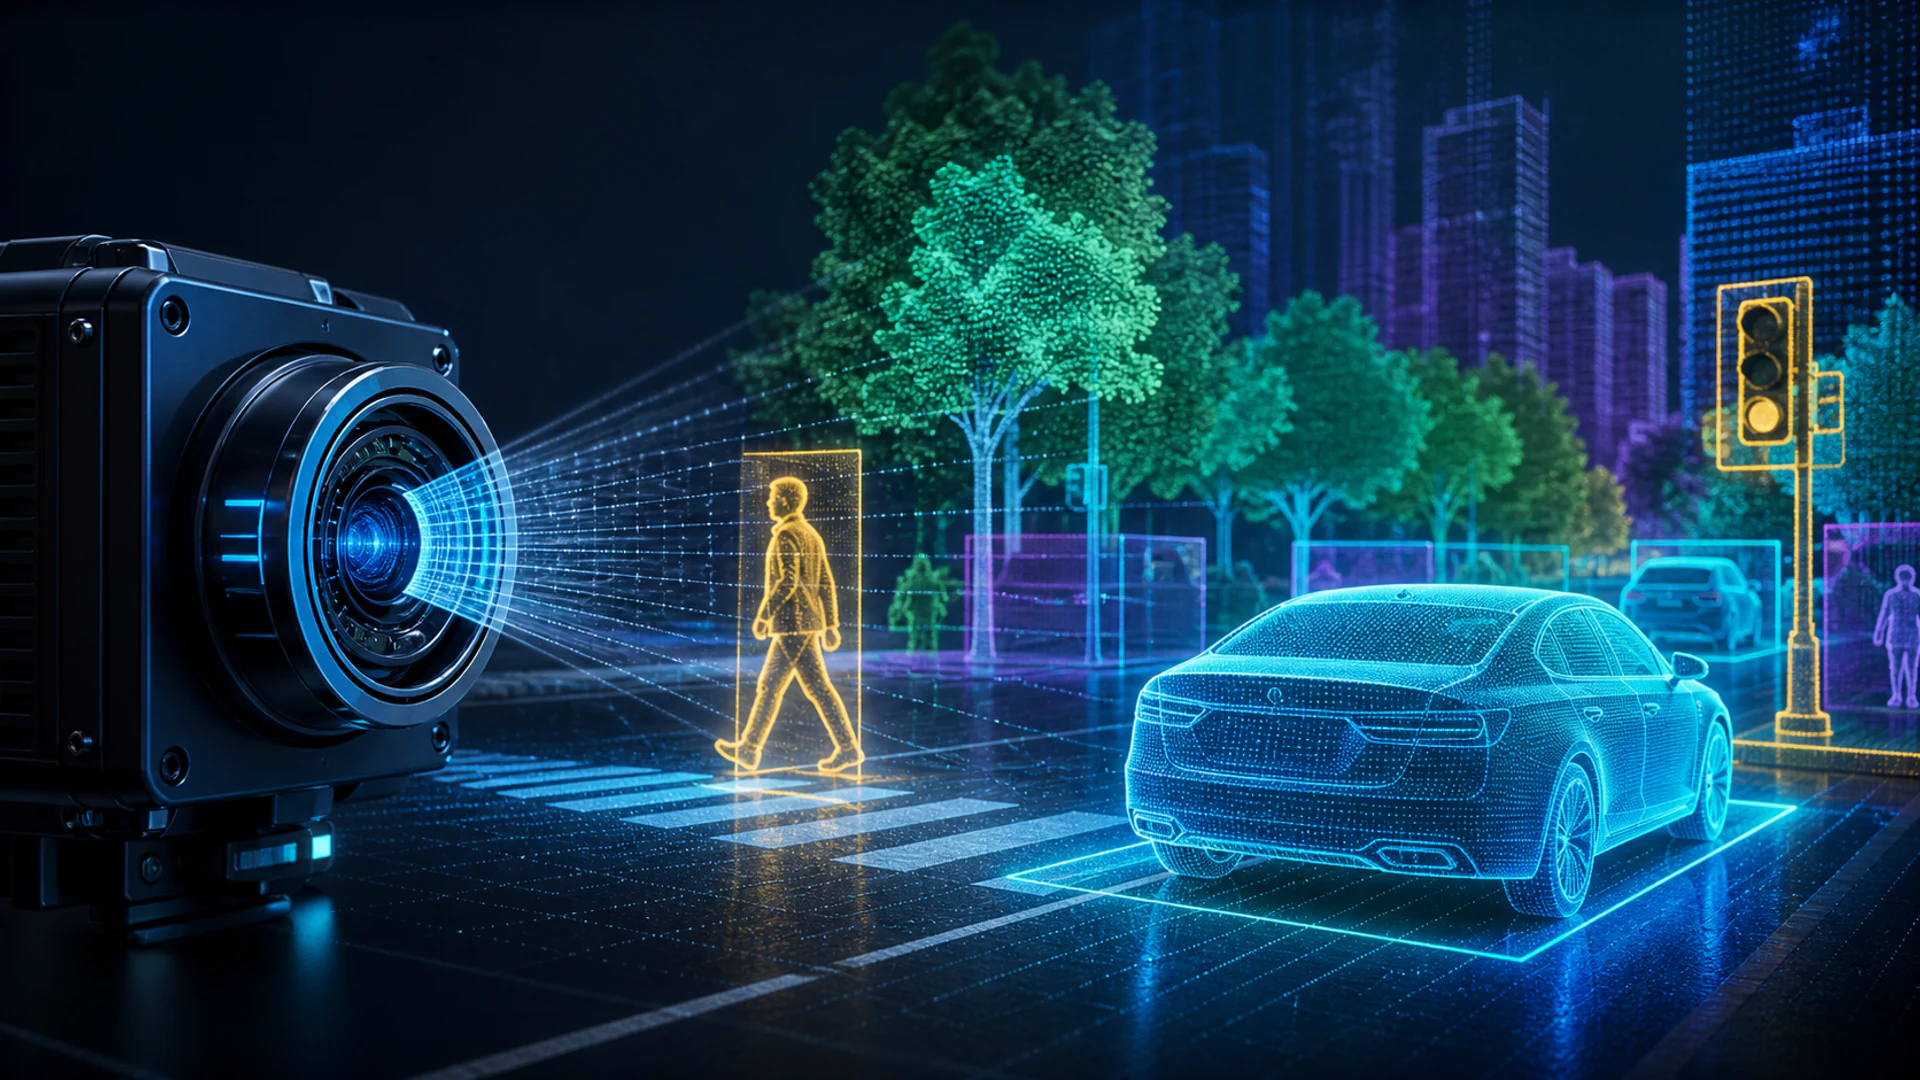
Computer vision is the field of building systems that extract useful information from images and video. A vision model might classify an entire image, locate objects, label every pixel, read text, estimate pose, track movement, or connect visual content with language.
Modern vision systems do not simply reproduce the early edge-detection process of human perception. They learn task-specific representations from data, often using convolutional neural networks, vision transformers, or multimodal foundation models.
Key takeaways
- Classification, detection, segmentation, OCR, tracking, and generation are distinct vision tasks.
- CNNs build in locality and weight sharing; vision transformers use attention across image patches.
- Labels can come from humans, weak supervision, synthetic data, or self-supervised objectives.
- Accuracy alone is insufficient: robustness, latency, privacy, bias, and failure costs matter.
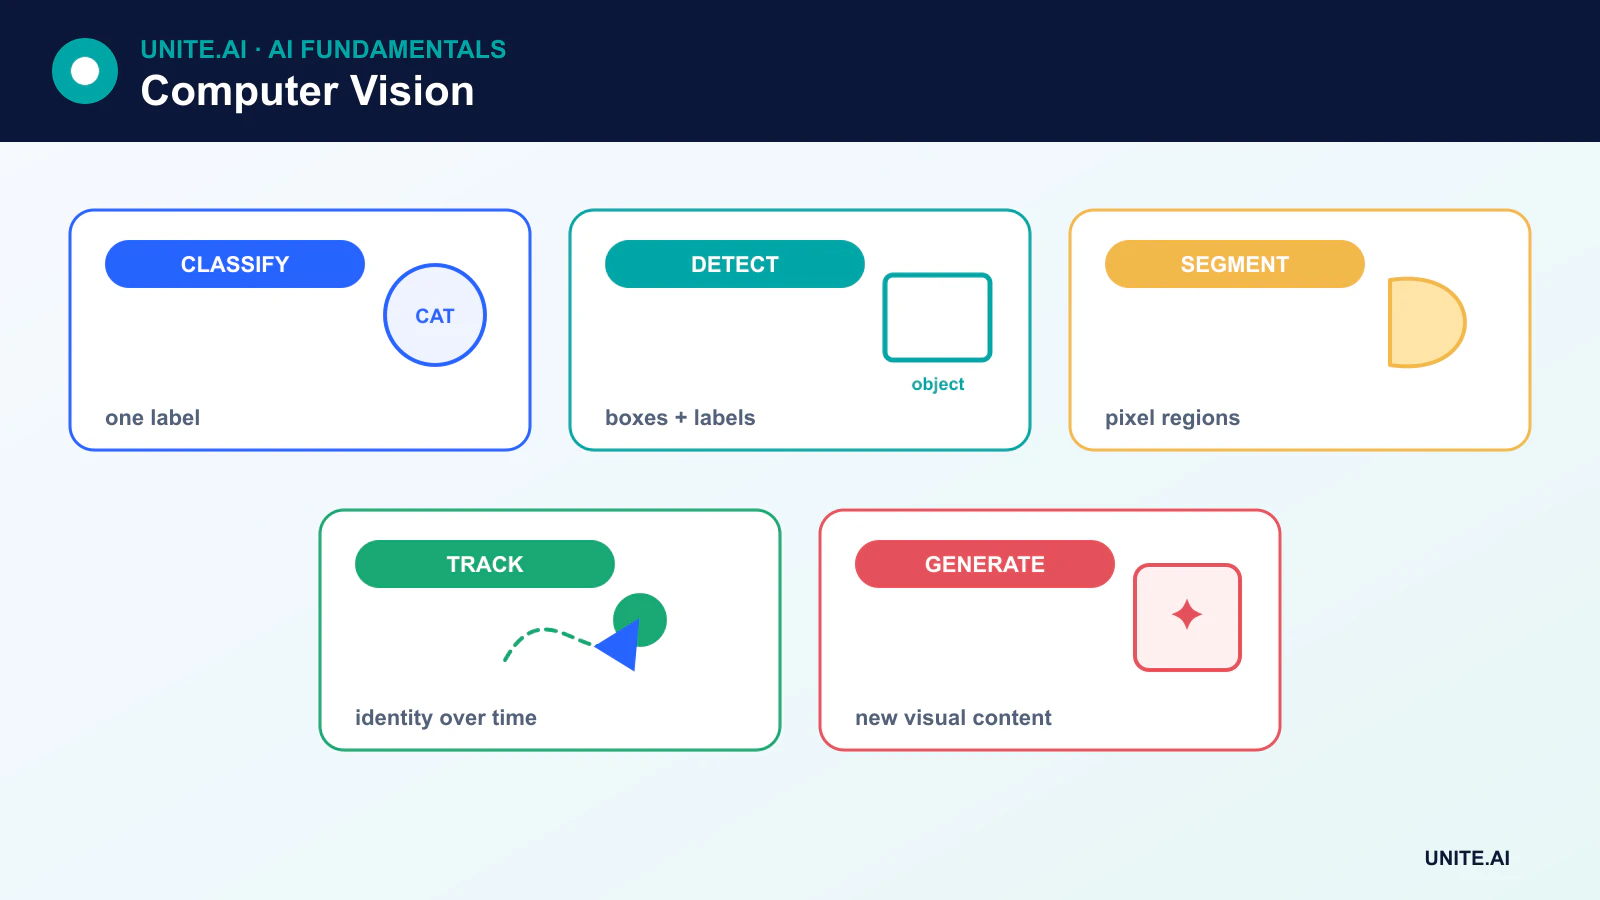
The main computer-vision tasks
- Image classification assigns one or more labels to an image. See how image classification works.
- Object detection predicts categories and bounding boxes for multiple objects.
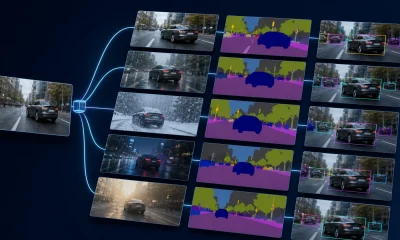
- Semantic segmentation labels each pixel by class, while instance segmentation separates individual objects.
- Optical character recognition (OCR) detects and transcribes text.
- Pose estimation predicts body or object landmarks.
- Tracking associates detections across video frames.
- Image generation and editing produce or transform visual content, often using diffusion models.
How images become model inputs
A digital image is already numerical data: a tensor containing pixel values across spatial dimensions and channels. Preprocessing may resize, normalize, crop, or augment the image. Video adds a time dimension, while medical and scientific imaging can add depth, wavelength, or other modalities.
Classical computer vision used hand-designed edge, corner, and texture features. Modern deep models usually learn features jointly with the task, though classical methods remain useful when data is limited, rules are well understood, or compute must be minimal.
CNNs and learned local features
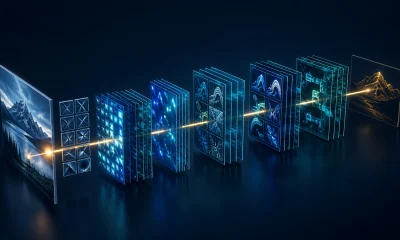
A CNN applies learned kernels across local neighborhoods. Early layers can respond to local patterns, while later blocks combine them into task-relevant representations. Pooling or strided operations reduce spatial resolution, and residual connections make deep networks easier to optimize.
A modern CNN classifier often uses global pooling rather than a large stack of fully connected layers. Detectors and segmentation networks add specialized heads or decoder paths that preserve spatial information.
Vision transformers and foundation models
A vision transformer divides an image into patches, embeds them, and uses attention to model their relationships. Transformers can scale effectively with large datasets and pretraining, while CNNs often provide stronger built-in assumptions and efficiency at smaller scales.
Multimodal models align images with text so users can search, caption, answer questions, or guide segmentation using language. These models expand capability but also inherit weaknesses from broad web-scale data, including stereotypes, copyrighted material, and uneven coverage of populations and environments.
Labels, self-supervision, and synthetic data
Bounding boxes, masks, landmarks, and captions can be expensive to create. Self-supervised learning derives objectives from the images themselves, while weak supervision uses noisy or indirect labels. Synthetic data can add rare scenarios, but simulation gaps may prevent synthetic performance from transferring to the real world.
Annotation quality must be measured. Ambiguous labels, inconsistent boundaries, and missing objects place a ceiling on performance and can hide subgroup failures.
How vision systems are evaluated
Classification uses metrics such as accuracy, precision, recall, F1, and calibration. Detection commonly uses intersection over union and mean average precision. Segmentation uses intersection over union or Dice-style measures. Tracking adds identity and trajectory metrics.
The metric must match deployment. A model can score well on a curated benchmark and still fail in rain, low light, unusual camera angles, new devices, or unfamiliar populations. Evaluation should include distribution shift, adversarial conditions, and operational latency.
Privacy, bias, and deployment
Faces, license plates, homes, medical scans, and workplace video can reveal sensitive information. Collection and retention should follow a defined legal and ethical basis, with access controls and data minimization. Facial analysis and biometric identification deserve particular scrutiny because errors and surveillance can impose unequal harms.
Edge deployment can reduce latency and data transfer. Edge AI, quantization, pruning, and specialized accelerators can make vision systems practical on cameras, vehicles, robots, and mobile devices, but compression must be re-evaluated for accuracy and bias.
From pixels to visual tasks
Computer vision turns images or video into task outputs such as classification, detection, segmentation, tracking, pose, depth, optical flow, or text recognition. The task definition determines annotation: an image label cannot train precise localization, and a bounding box cannot fully describe a segmentation mask. Camera geometry, lenses, exposure, lighting, motion, compression, and viewpoint shape the data distribution. Define the operating environment and error consequence before selecting a model, because a benchmark image collection may not represent the deployed sensor or scene.
A pipeline decodes and orients media, resizes or tiles it, normalizes values, applies label-preserving augmentation, runs a model, and postprocesses logits, boxes, masks, or tracks. Object detectors use confidence thresholds and suppression; trackers associate detections over time; segmentation may require morphological cleanup. Preserve coordinate transforms so outputs align with the original image. Split data by person, camera, location, or capture session to avoid nearly identical frames appearing in both training and test sets.
Evaluation, bias, privacy, and operations
Metrics must match the task and use. Classification needs class-specific precision and recall; detection uses intersection-over-union and average precision across thresholds; segmentation uses IoU or Dice; tracking adds identity switches; latency and missed-event duration matter for video. Report results by lighting, distance, device, occlusion, skin tone, age, and other relevant conditions. Inspect calibration and high-confidence errors. Synthetic or augmented data can fill gaps but requires comparison with real deployment data and must not leak test scenes.
Vision can collect bystanders, locations, biometrics, and sensitive behavior. Minimize capture and retention, secure streams, restrict secondary use, and provide notice or consent where required. Test adversarial patches, replay, occlusion, camera failure, and domain shift. Monitor sensor health, input statistics, output rates, and confirmed outcomes; keep human review for consequential decisions. Blur or cropping can reduce exposure but may also remove evidence. A high laboratory score does not justify identity, emotion, or intent claims beyond the validated task.
Worked example: pedestrian detection at a warehouse crossing
Cameras monitor a restricted vehicle crossing, and the model detects people rather than identifying them. Data covers day and night, weather, clothing, occlusion, wheelchair users, camera positions, and empty scenes, split by recording session. The detector is evaluated for event recall, false alarms, localization, warning lead time, and performance at distance. Safety engineering defines the maximum tolerated latency and independent physical controls.
The vision alert can slow a vehicle, but emergency stops and barriers do not depend on the learned model. Camera obstruction, frozen frames, network loss, and model timeout produce explicit faults. Raw video retention is minimized and access logged. Monitoring tracks sensor health, alert rates, reviewed incidents, and near misses by condition. Any camera relocation or layout change triggers revalidation because apparent image similarity does not guarantee the same geometry or risk.
Implementation evidence and operational readiness
A production decision needs more than a successful demonstration. Define the intended users, operating environment, inputs, outputs, dependencies, owner, and the consequence of each important failure. Establish a reproducible baseline and a versioned evaluation set before tuning. Test ordinary cases, boundary conditions, malformed or missing input, distribution shift, dependency outage, misuse, and the groups or environments most likely to be underserved. Measure task quality together with calibration or uncertainty, latency, throughput, resource cost, accessibility, privacy, and security. Record every transformation and threshold so an independent reviewer can reproduce the result and distinguish evidence from an attractive prototype.
Before launch, assign authority for release, exceptions, changes, rollback, and retirement. Use a staged rollout, preserve a safe fallback, and verify monitoring with deliberately injected failures. Operational telemetry should reveal input quality, output behavior, model or rule version, dependency health, human overrides, and confirmed outcomes without collecting unnecessary sensitive data. Define alert thresholds and a response owner, then review real-world evidence after deployment rather than assuming offline performance will persist. Reevaluate whenever data sources, users, models, vendors, policies, hardware, or objectives change. A maintained system also needs documented recovery, incident learning, deletion and retention procedures, and a clear point at which it should be disabled or replaced.
Frequently asked questions
Is computer vision the same as image recognition?
No. Image recognition usually refers to classification or identification. Computer vision also includes localization, segmentation, measurement, tracking, reconstruction, generation, and reasoning over visual information.
Does a vision system see like a human?
No. A model processes numerical inputs according to its architecture and training objective. It can outperform people on a narrow benchmark while failing on small changes that a person handles easily.
Primary references