AI Fundamentals
What is Federated Learning?

 Add Unite.AI to your preferred sources on Google
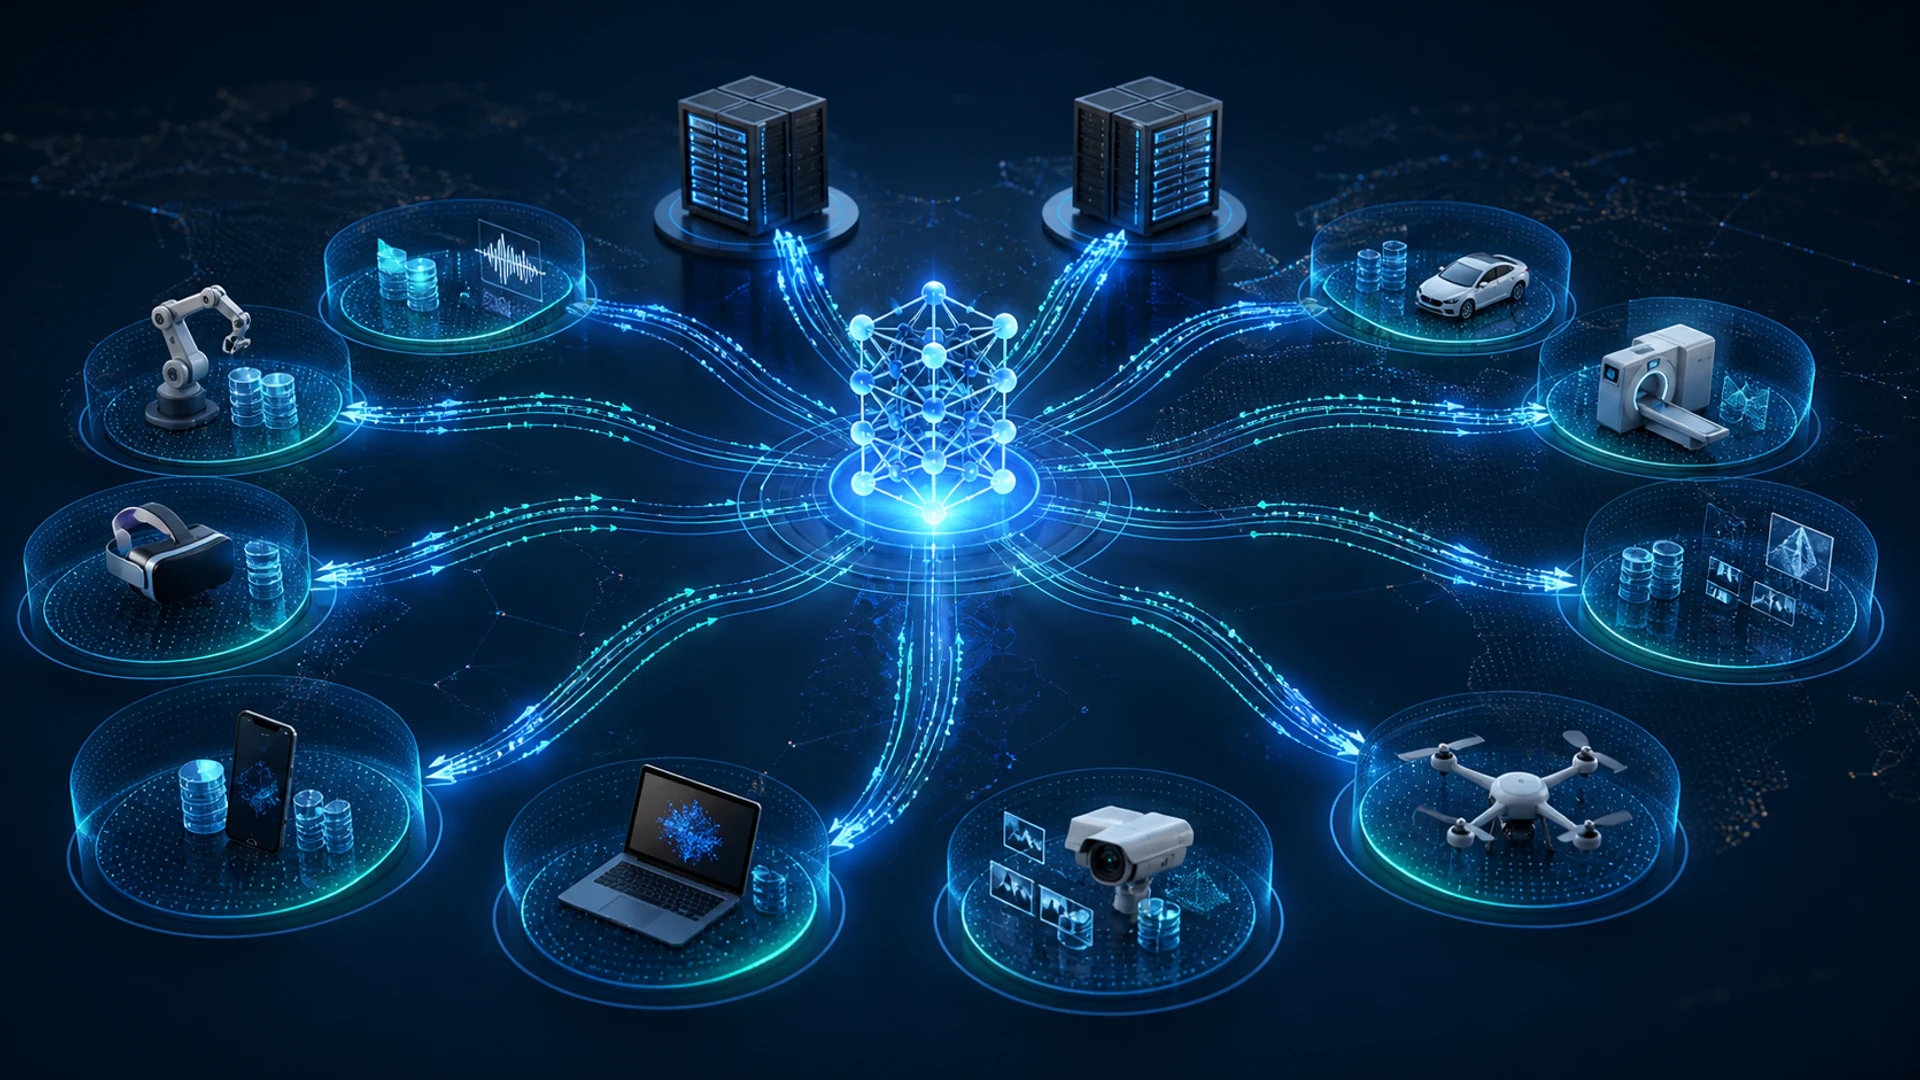
Federated learning trains a shared model across multiple devices or organizations while keeping each participant’s raw training data local. A coordinator distributes model parameters, clients compute updates on their own records, and an aggregation step combines those updates.
Keeping records local is useful, but it is not synonymous with privacy or security. Model updates can leak information, compromised clients can poison training, and the coordinator still needs authentication, transport security, access controls and a defined trust model.
Key takeaways
- Federated learning moves computation to distributed data; it does not move the raw dataset to one central trainer.
- Cross-device systems involve many intermittent devices, while cross-silo systems involve fewer, more stable organizations.
- Secure aggregation and differential privacy address different risks and can be combined.
- Non-IID data, limited bandwidth, unreliable participation and malicious updates are core design constraints.
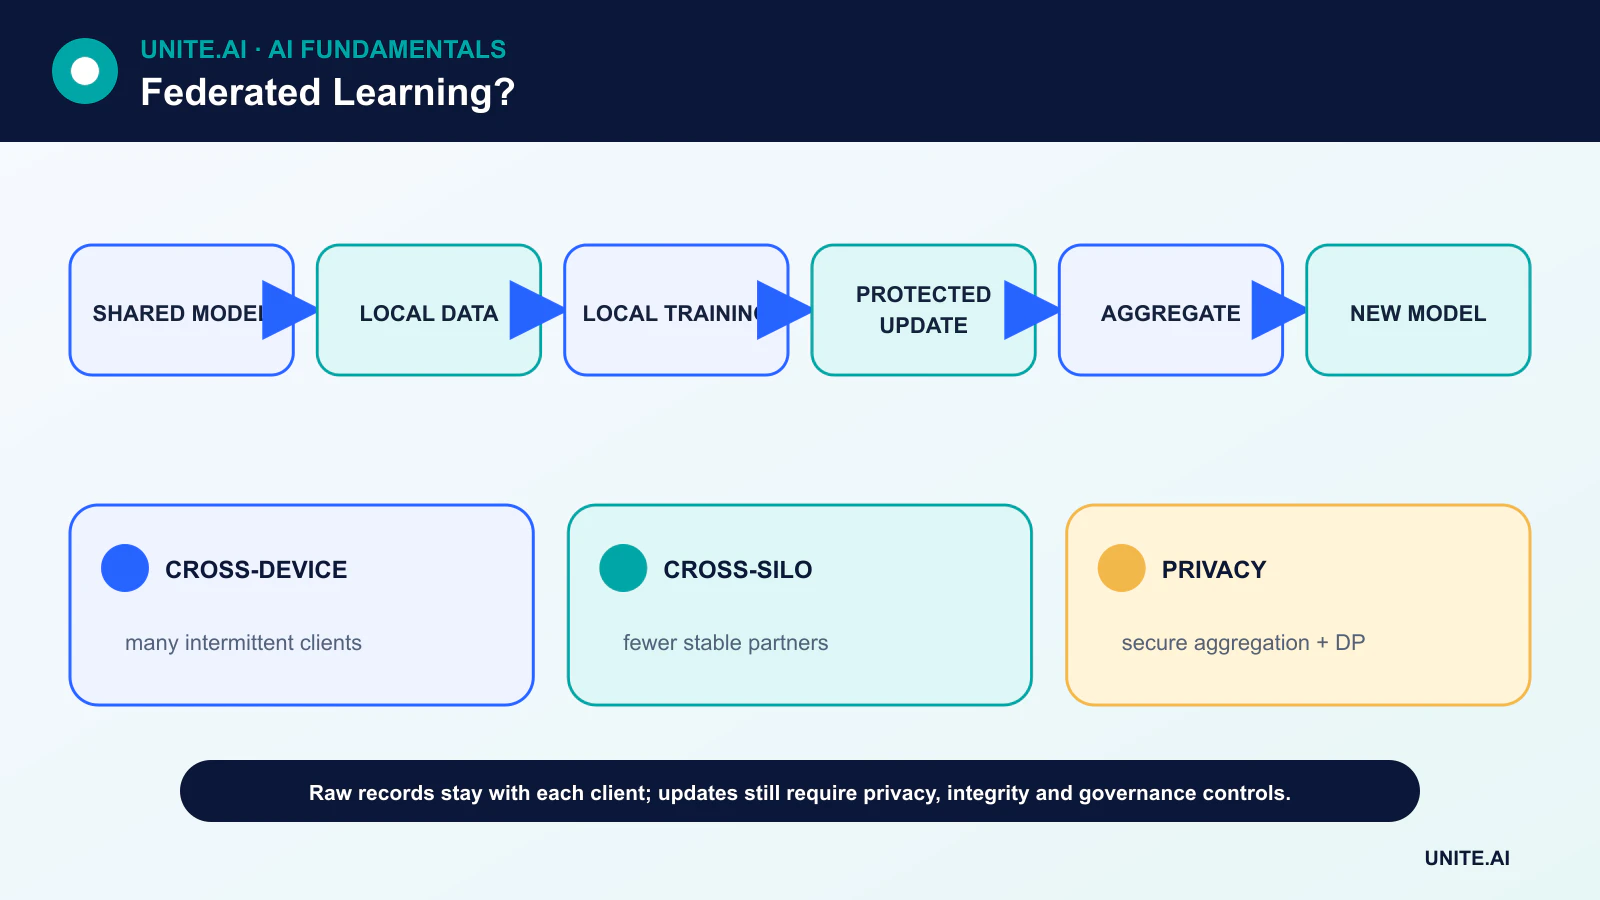
The federated averaging lifecycle
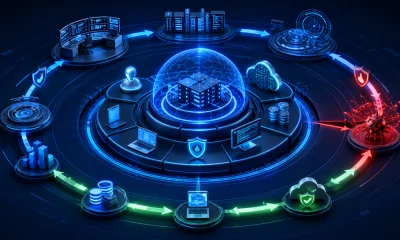
A typical round begins when a coordinator selects eligible clients and sends the current model. Each client trains locally for a limited number of steps, producing a parameter or gradient update. The coordinator aggregates eligible updates—often with weights based on local example counts—and publishes the new shared model.
Only a fraction of clients may participate in each round. The protocol must tolerate dropped connections, version mismatches and devices that cannot train while charging, busy or offline. Communication can dominate computation, so update compression and fewer round trips often matter more than raw accelerator speed.
Cross-device versus cross-silo
Cross-device federated learning may involve phones, sensors or browsers owned by many individuals. Clients are numerous, weakly trusted and intermittently available. Cross-silo federated learning usually connects a smaller set of hospitals, banks or business units with stable infrastructure and contractual governance.
The two settings require different identity, audit and failure assumptions. A cross-silo project can negotiate a shared schema and validation process; a cross-device service may have to handle millions of software versions and highly uneven local datasets.
Secure aggregation, differential privacy and encryption
Secure aggregation is a cryptographic protocol that lets the server recover an aggregate without reading each client’s update. Differential privacy limits how much the released result can depend on any one record or participant by clipping contributions and adding calibrated noise.
Neither mechanism fixes every risk. Secure aggregation does not make the aggregate harmless, and differential privacy imposes an accuracy–privacy tradeoff that must be accounted for with an explicit privacy budget. Encryption protects data in transit or storage; it does not by itself prevent inference from a model.
Non-IID data and model quality
Client data are rarely independent and identically distributed. A keyboard model sees each person’s vocabulary; hospitals serve different populations; factories use different equipment. These differences can slow convergence and can hide poor performance for small client groups.
Evaluation should include global metrics, per-client or cohort distributions, calibration and failure analysis. A central test set may be convenient but insufficient. This connects federated learning to machine-learning data quality and structured and unstructured data governance.
Threats and operational controls
Malicious clients can submit poisoned updates, sybil clients can distort aggregation, and a compromised server can distribute a targeted model. Defenses include authenticated enrollment, anomaly detection, robust aggregation, update validation, rate limits and reproducible software attestation where practical.
Federated learning belongs inside a broader cybersecurity program. Teams should document who controls the coordinator, what metadata are collected, how participants can leave, how models are rolled back and what happens when privacy or quality tests fail.
Federated optimization and data heterogeneity
Federated learning sends a model or update task to participating clients, trains locally, and aggregates updates without centralizing raw examples. In federated averaging, selected clients run several local optimization steps and the server computes a weighted average, commonly by example count. Communication rounds, local epochs, selection, and learning rates trade bandwidth against convergence. Cross-device settings involve many unreliable phones or sensors; cross-silo settings involve fewer organizations with stronger compute, identity, and governance.
Client data is usually non-independent and uneven: users differ in behavior, label distribution, volume, and availability. Local training can drift in incompatible directions, making a simple average unstable or biased toward active high-volume clients. Algorithms may use proximal terms, adaptive server optimization, clustering, personalization, or control variates. Evaluation should report global and client-level performance, tail clients, participation frequency, convergence, communication, and energy. A good average can conceal that small or rare client populations receive a worse model.
Privacy, security, and systems engineering
Keeping data local does not by itself guarantee privacy. Gradients and updates can leak membership or features, while the final model can memorize examples. Secure aggregation hides individual updates from the server, and differential privacy bounds information contribution by clipping and adding noise, but both change utility and operational complexity. State the threat model, privacy unit, budget, and trusted components. Encryption in transit is necessary but does not prevent a malicious client, poisoned update, compromised coordinator, or inference attack.
Defenses include authenticated clients, robust aggregation, anomaly checks, update limits, secure enclaves in some designs, and validation against clean data. Sybil attackers can create many clients; backdoors can survive averaging; dropping suspicious updates can also exclude legitimate rare behavior. Version client code, support interrupted rounds, prevent replay, and design for stragglers and device constraints. Consent, retention, regional rules, and deletion still apply to local data and derived updates.
Deployment and governance example
A mobile keyboard can train next-word improvements locally, but rollout should use a population eligible by device capability and consent, collect clipped protected updates, and compare with a frozen baseline. Validate language and dialect performance, battery, data use, and memorization risk before release. Clients need signed training tasks and model updates; the server needs auditable round configuration and rollback. Federated learning is an architecture for distributed learning under constraints, not a substitute for representative data, privacy engineering, or accountability.
Worked example: federated learning across hospitals
Hospitals train a shared image-quality model without pooling scans. A common protocol defines device metadata, labels, preprocessing, client eligibility, local epochs, clipping, and secure aggregation. Sites retain patient data and submit protected updates, while a coordinator evaluates each round on local held-out sets. Results report site-level and tail performance, not only a volume-weighted average, because small hospitals and device types may otherwise be ignored.
The threat model covers malicious updates, membership leakage, compromised clients, and coordinator access. Differential privacy is configured with a documented budget and tested utility. Model and task packages are signed; sites can withdraw and updates are auditable. A poisoned or unstable round does not replace the deployed model automatically. The project retains local baselines and clinical review, and it treats federated architecture as one privacy control within broader consent, security, and governance obligations.
Implementation evidence and operational readiness
A production decision needs more than a successful demonstration. Define the intended users, operating environment, inputs, outputs, dependencies, owner, and the consequence of each important failure. Establish a reproducible baseline and a versioned evaluation set before tuning. Test ordinary cases, boundary conditions, malformed or missing input, distribution shift, dependency outage, misuse, and the groups or environments most likely to be underserved. Measure task quality together with calibration or uncertainty, latency, throughput, resource cost, accessibility, privacy, and security. Record every transformation and threshold so an independent reviewer can reproduce the result and distinguish evidence from an attractive prototype.
Before launch, assign authority for release, exceptions, changes, rollback, and retirement. Use a staged rollout, preserve a safe fallback, and verify monitoring with deliberately injected failures. Operational telemetry should reveal input quality, output behavior, model or rule version, dependency health, human overrides, and confirmed outcomes without collecting unnecessary sensitive data. Define alert thresholds and a response owner, then review real-world evidence after deployment rather than assuming offline performance will persist. Reevaluate whenever data sources, users, models, vendors, policies, hardware, or objectives change. A maintained system also needs documented recovery, incident learning, deletion and retention procedures, and a clear point at which it should be disabled or replaced.
Frequently asked questions
Does federated learning guarantee that private data cannot leak?
No. It reduces raw-data movement, but updates and final models can still reveal information. Privacy requires a threat model and additional technical and organizational controls.
When is centralized training simpler?
When data can be lawfully and safely centralized, centralized training is often easier to debug, reproduce and monitor. Federated learning is justified when distribution is a real requirement, not merely a branding goal.
Primary references