AI Fundamentals
What is Vector Similarity Search and How Does It Work?

 Add Unite.AI to your preferred sources on Google
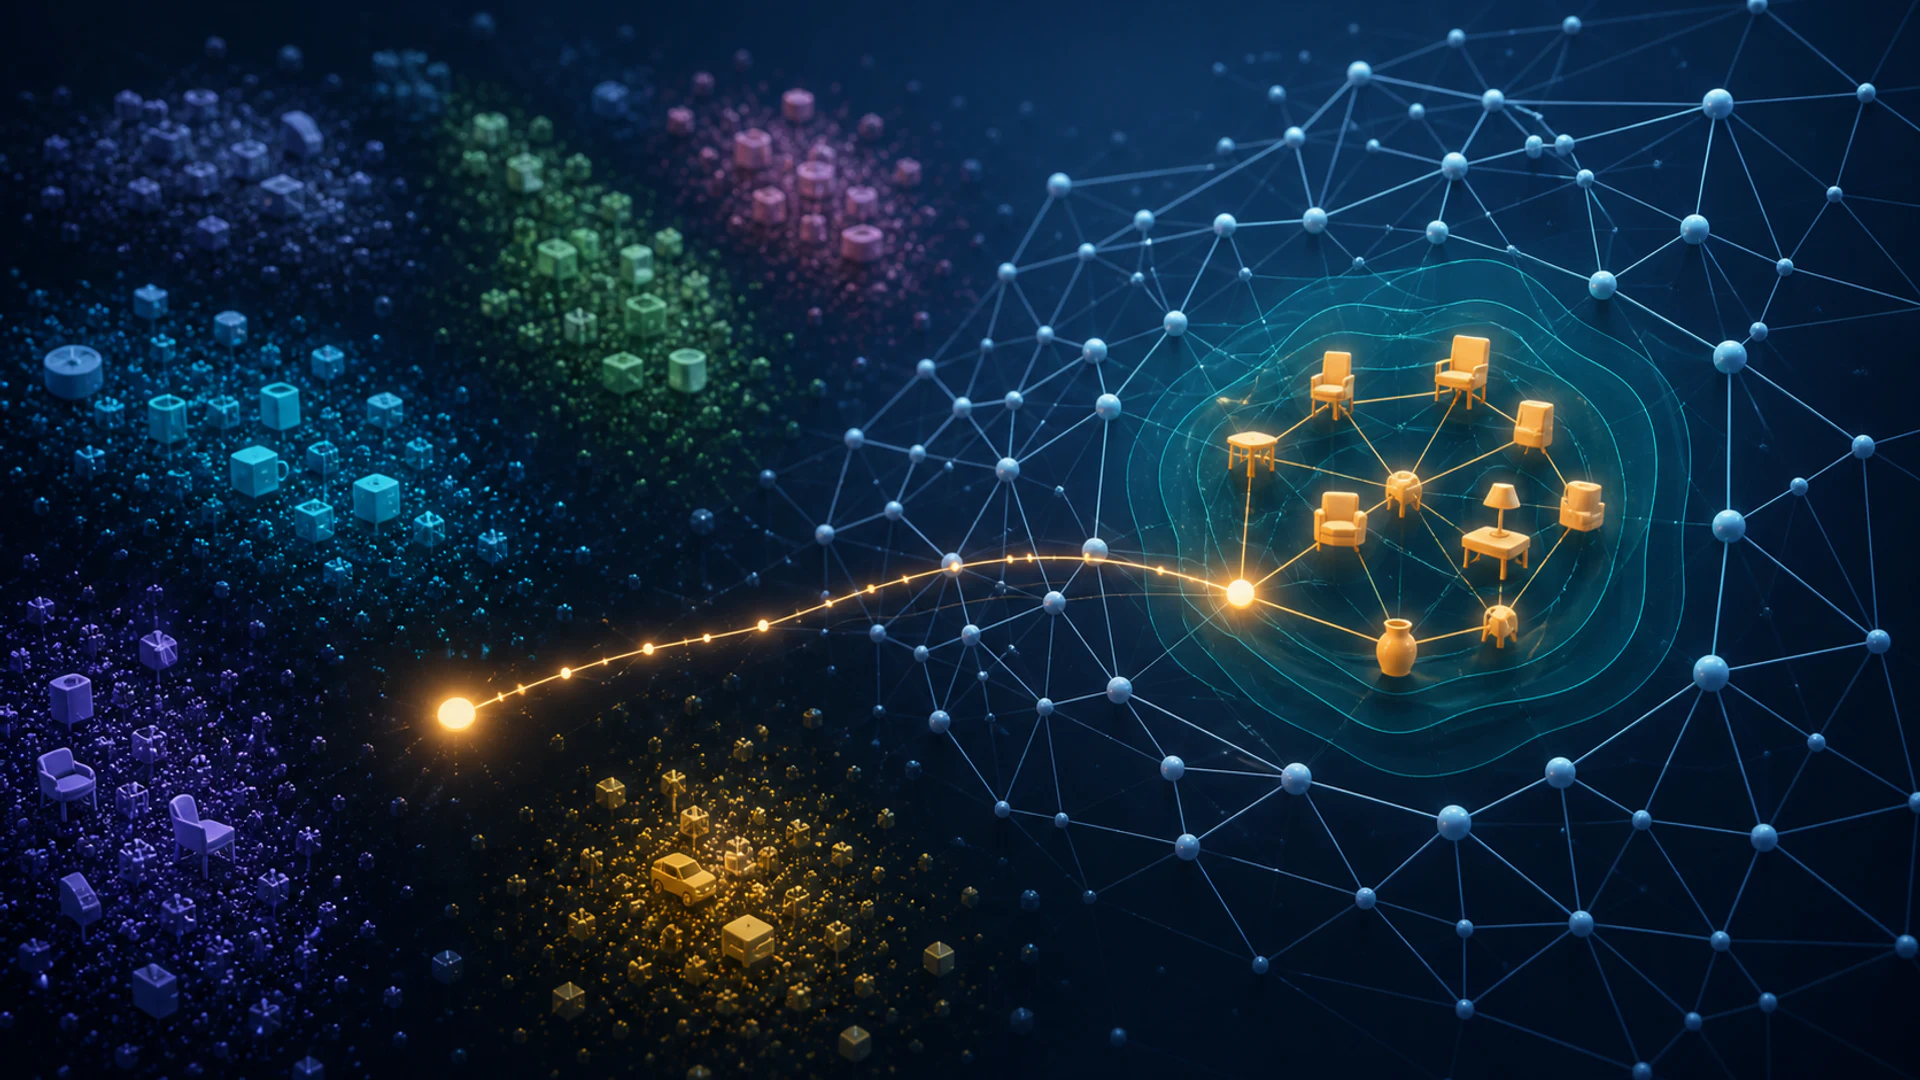
Vector similarity search finds items whose numeric representations are close to a query vector under a chosen distance or similarity function. An embedding model maps text, images, audio, products or users into vectors so related items can occupy nearby regions of the representation space.
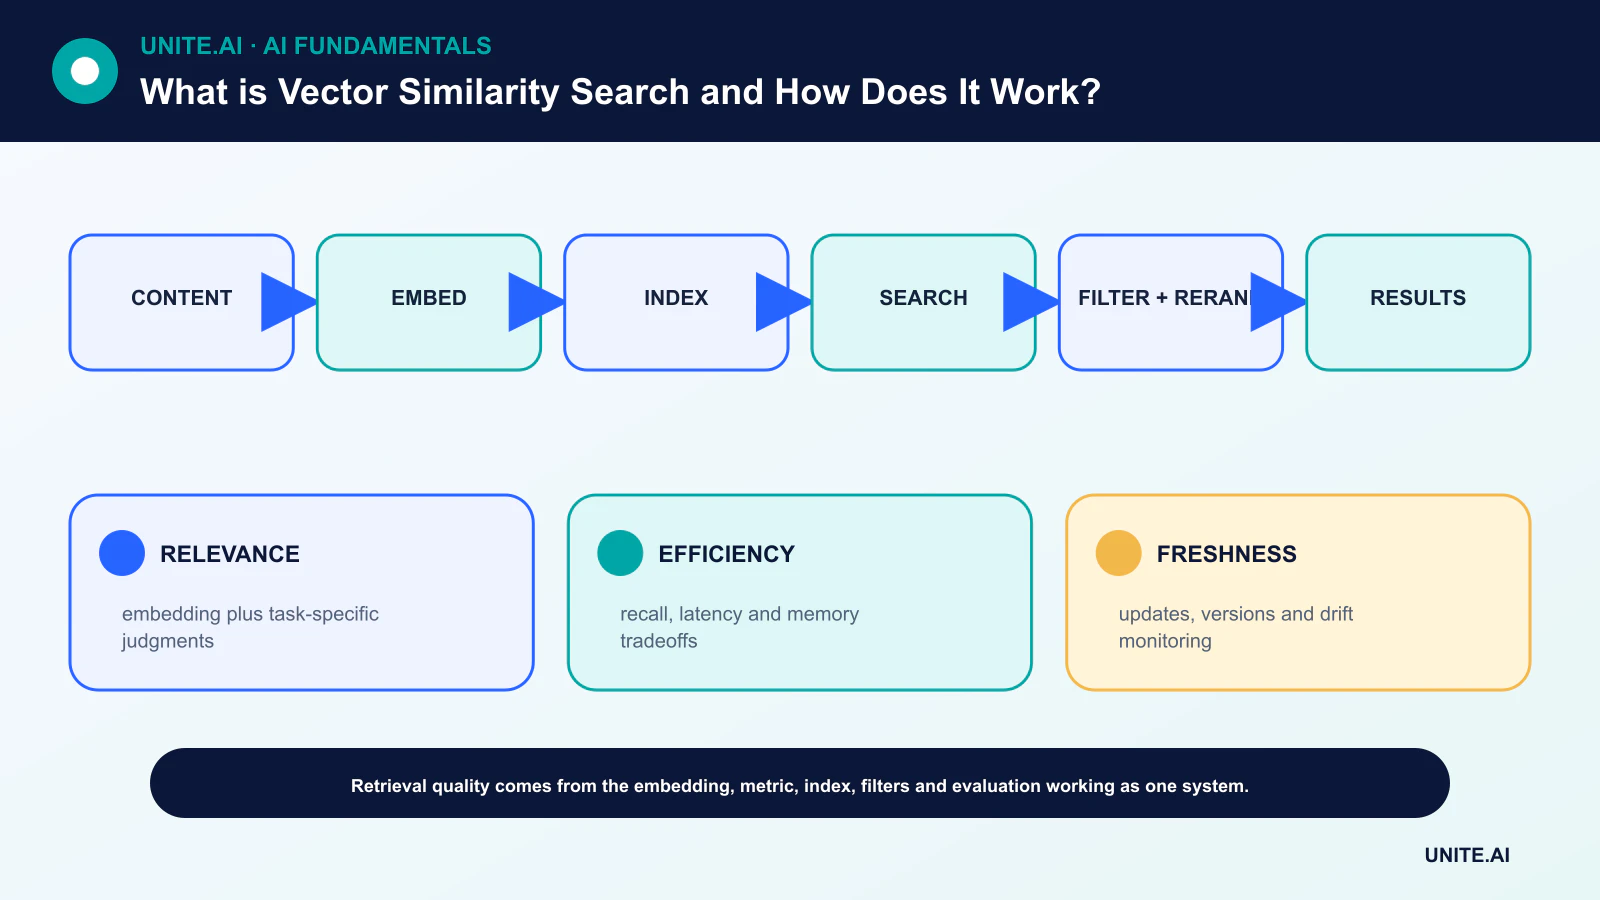
The search index does not understand similarity independently of the embedding and metric. If the representation encodes the wrong notion of relevance, a fast nearest-neighbor algorithm will return the wrong neighbors efficiently.
Key takeaways
- Embedding model, preprocessing and distance metric define what close means.
- Exact k-nearest-neighbor search scans all candidates; approximate indexes trade some recall for speed and memory.
- HNSW, inverted-file indexes and product quantization offer different build, query and update tradeoffs.
- Metadata filtering, hybrid retrieval and reranking are part of the system, not afterthoughts.
Embeddings and similarity metrics
A transformer or other encoder converts an item into a fixed-length vector. Cosine similarity compares angle, dot product combines direction and magnitude, and Euclidean distance measures straight-line separation.
Normalization can make cosine similarity and dot product rankings equivalent. The metric used to train the embedding should match retrieval. Evaluate domain-specific relevance because semantic similarity, substitutability and user preference are different objectives.
Exact versus approximate search
Exact search computes similarity to every eligible vector and returns the true nearest candidates. It is simple and accurate but becomes expensive as the collection, dimension or query rate grows.
Approximate nearest-neighbor (ANN) indexes examine a smaller candidate set. Measure recall@k against exact ground truth along with latency, throughput and memory. Approximate describes the search algorithm, not whether the embedding itself is correct.
HNSW, inverted files and compression
Hierarchical Navigable Small World graphs connect vectors in layers. A query descends from sparse long-range links to dense local links. Search breadth controls a recall–latency tradeoff, while graph construction and updates consume memory.
Inverted-file indexes use coarse clustering—often related to K-means—to search selected regions. Product quantization compresses vector subspaces, reducing memory at the cost of distance error. Faiss combines several such techniques.
Filtering, hybrid retrieval and reranking
Real queries often require tenant, language, date, permission or product filters. Pre-filtering can leave too few graph candidates; post-filtering can waste retrieval work. Index and query plans should be tested at realistic filter selectivity.
Hybrid search combines lexical matching with vector similarity so exact names and semantic meaning both contribute. A reranker can apply a more expensive cross-encoder or business rules to the top candidates. Preserve authorization checks through every stage.
Evaluation, updates and drift
Use labeled relevance judgments or downstream task success, not visual clusters alone. Track recall, precision, normalized discounted cumulative gain, latency percentiles, memory, index build time and freshness.
Embedding-model upgrades require re-embedding and can move every point. Version vectors and indexes, support dual-run migration and monitor query/population drift. Dimensionality reduction can aid visualization but may distort neighborhoods and should not be mistaken for retrieval evaluation.
Embeddings, metrics, and index structures
Vector similarity search represents items as numeric embeddings and retrieves vectors close to a query under a metric such as cosine similarity, dot product, or Euclidean distance. The embedding model defines what closeness means; the index only accelerates that geometry. Normalize vectors when required, preserve model and preprocessing version, and do not compare distances from incompatible embedding spaces. A strong model for general semantics may fail on product compatibility, legal citation, images, code, or multilingual terminology without domain evaluation.
Exact search compares every vector and is simple but expensive at scale. Approximate nearest-neighbor methods trade recall for speed and memory. Graph indexes such as HNSW navigate linked neighbors; inverted-file methods partition vectors into coarse cells; product quantization compresses vectors; disk-based methods trade storage and latency. Build-time, query-time, and memory parameters interact. Benchmark on production-like vector count, dimension, updates, filters, concurrency, and hardware.
Retrieval quality and hybrid search
Create judged queries with relevant and nonrelevant items, including rare terms, ambiguity, long text, languages, and freshness. Measure recall@k, precision@k, mean reciprocal rank, normalized discounted gain, latency, and cost. Separately measure ANN recall against exact neighbors and semantic relevance against human judgments. A fast index can retrieve the mathematically nearest wrong items if the embedding is poor.
Keyword search remains strong for exact names, identifiers, dates, and rare tokens. Hybrid retrieval combines lexical and vector rankings, while metadata filters enforce tenant, permission, language, date, and type. Apply authorization before returning or generating from results; filtering after retrieval can leak existence or content. Rerankers improve precision at added latency. Chunking should follow document structure and preserve source, version, and offsets for citation.
Production lifecycle
Updates need deterministic IDs, delete propagation, tombstones or compaction, and a strategy for re-embedding after model changes. Never mix old and new embeddings silently; rebuild or version indexes and compare offline before cutover. Monitor query and result distributions, empty and low-score searches, latency, index health, and judged feedback. Protect embeddings because they can encode sensitive information and enable inference. Vector search is retrieval infrastructure, not a guarantee of factuality; downstream systems must preserve evidence and abstain when support is inadequate.
Worked example: permission-aware vector retrieval
An enterprise chunks manuals by section, embeds them with a versioned model, and stores document ID, permissions, language, version, and offsets. A judged query set compares lexical, vector, hybrid, and reranked retrieval. Evaluation measures recall and precision at k, citation coverage, latency, cost, and results for exact part numbers and multilingual terminology. ANN recall is separately checked against exact vector neighbors.
At query time, authorization filters candidates before content is returned. Low-scoring searches abstain, and the answer layer cites source sections and states conflicts. Re-embedding builds a new index rather than mixing vector versions, and delete events remove source, chunks, and cache. Monitoring tracks empty queries, score and latency distributions, permission denials, and reviewed relevance. Embeddings are protected as sensitive derived data. Similarity retrieves evidence; it does not establish that the evidence is true or applicable.
Implementation evidence and operational readiness
A production decision needs more than a successful demonstration. Define the intended users, operating environment, inputs, outputs, dependencies, owner, and the consequence of each important failure. Establish a reproducible baseline and a versioned evaluation set before tuning. Test ordinary cases, boundary conditions, malformed or missing input, distribution shift, dependency outage, misuse, and the groups or environments most likely to be underserved. Measure task quality together with calibration or uncertainty, latency, throughput, resource cost, accessibility, privacy, and security. Record every transformation and threshold so an independent reviewer can reproduce the result and distinguish evidence from an attractive prototype.
Before launch, assign authority for release, exceptions, changes, rollback, and retirement. Use a staged rollout, preserve a safe fallback, and verify monitoring with deliberately injected failures. Operational telemetry should reveal input quality, output behavior, model or rule version, dependency health, human overrides, and confirmed outcomes without collecting unnecessary sensitive data. Define alert thresholds and a response owner, then review real-world evidence after deployment rather than assuming offline performance will persist. Reevaluate whenever data sources, users, models, vendors, policies, hardware, or objectives change. A maintained system also needs documented recovery, incident learning, deletion and retention procedures, and a clear point at which it should be disabled or replaced.
Frequently asked questions
Is a vector database required for similarity search?
No. Libraries and relational databases can support vector indexes. A specialized database is useful when its scale, filtering, durability and operational features fit the workload.
Does a higher-dimensional embedding always perform better?
No. More dimensions increase cost and may encode noise. Compare models on representative retrieval quality, latency and storage.
Primary references