Key PointsTwo-stage retrieval with rerankers dramatically improves RAG accuracy by first fetching… View more
Two-stage retrieval with rerankers dramatically improves RAG accuracy by first fetching many documents then reordering them with a smarter model.
ColBERT's late interaction mechanism enables efficient semantic search by processing queries and documents separately until the final comparison.
Reranking models can be trained on domain-specific data to solve the out-of-domain problems common in general embedding models.
When it comes to natural language processing (NLP) and information retrieval, the ability to efficiently and accurately retrieve relevant information is paramount. As the field continues to evolve, new techniques and methodologies are being developed to enhance the performance of retrieval systems, particularly in the context of Retrieval Augmented Generation (RAG). One such technique, known as two-stage retrieval with rerankers, has emerged as a powerful solution to address the inherent limitations of traditional retrieval methods.
In this article we discuss the intricacies of two-stage retrieval and rerankers, exploring their underlying principles, implementation strategies, and the benefits they offer in enhancing the accuracy and efficiency of RAG systems. We’ll also provide practical examples and code snippets to illustrate the concepts and facilitate a deeper understanding of this cutting-edge technique.
Before diving into the specifics of two-stage retrieval and rerankers, let’s briefly revisit the concept of Retrieval Augmented Generation (RAG). RAG is a technique that extends the knowledge and capabilities of large language models (LLMs) by providing them with access to external information sources, such as databases or document collections. Refer more from the article “A Deep Dive into Retrieval Augmented Generation in LLM“.
The typical RAG process involves the following steps:
Query: A user poses a question or provides an instruction to the system.
Retrieval: The system queries a vector database or document collection to find information relevant to the user’s query.
Augmentation: The retrieved information is combined with the user’s original query or instruction.
Generation: The language model processes the augmented input and generates a response, leveraging the external information to enhance the accuracy and comprehensiveness of its output.
While RAG has proven to be a powerful technique, it is not without its challenges. One of the key issues lies in the retrieval stage, where traditional retrieval methods may fail to identify the most relevant documents, leading to suboptimal or inaccurate responses from the language model.
The Need for Two-Stage Retrieval and Rerankers
Traditional retrieval methods, such as those based on keyword matching or vector space models, often struggle to capture the nuanced semantic relationships between queries and documents. This limitation can result in the retrieval of documents that are only superficially relevant or miss crucial information that could significantly improve the quality of the generated response.
To address this challenge, researchers and practitioners have turned to two-stage retrieval with rerankers. This approach involves a two-step process:
Initial Retrieval: In the first stage, a relatively large set of potentially relevant documents is retrieved using a fast and efficient retrieval method, such as a vector space model or a keyword-based search.
Reranking: In the second stage, a more sophisticated reranking model is employed to reorder the initially retrieved documents based on their relevance to the query, effectively bringing the most relevant documents to the top of the list.
The reranking model, often a neural network or a transformer-based architecture, is specifically trained to assess the relevance of a document to a given query. By leveraging advanced natural language understanding capabilities, the reranker can capture the semantic nuances and contextual relationships between the query and the documents, resulting in a more accurate and relevant ranking.
Benefits of Two-Stage Retrieval and Rerankers
The adoption of two-stage retrieval with rerankers offers several significant benefits in the context of RAG systems:
Improved Accuracy: By reranking the initially retrieved documents and promoting the most relevant ones to the top, the system can provide more accurate and precise information to the language model, leading to higher-quality generated responses.
Mitigated Out-of-Domain Issues: Embedding models used for traditional retrieval are often trained on general-purpose text corpora, which may not adequately capture domain-specific language and semantics. Reranking models, on the other hand, can be trained on domain-specific data, mitigating the “out-of-domain” problem and improving the relevance of retrieved documents within specialized domains.
Scalability: The two-stage approach allows for efficient scaling by leveraging fast and lightweight retrieval methods in the initial stage, while reserving the more computationally intensive reranking process for a smaller subset of documents.
Flexibility: Reranking models can be swapped or updated independently of the initial retrieval method, providing flexibility and adaptability to the evolving needs of the system.
ColBERT: Efficient and Effective Late Interaction
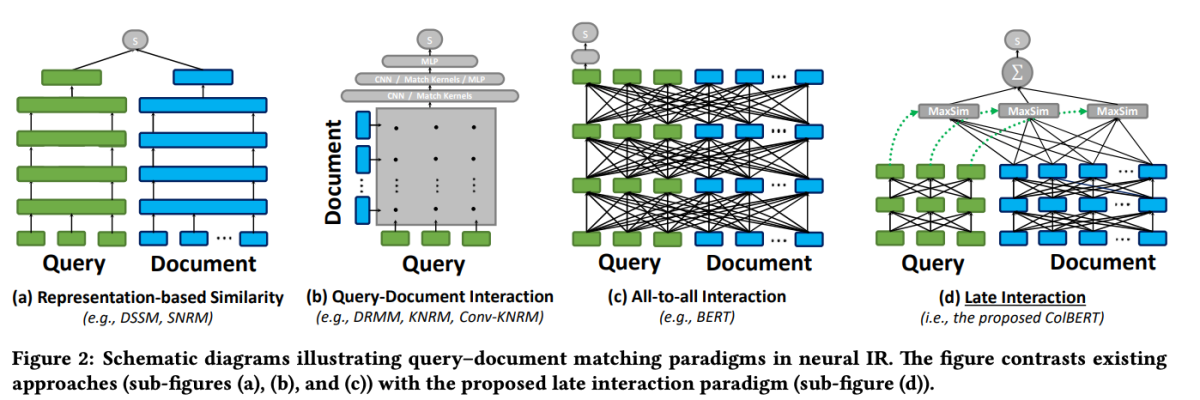
One of the standout models in the realm of reranking is ColBERT (Contextualized Late Interaction over BERT). ColBERT is a document reranker model that leverages the deep language understanding capabilities of BERT while introducing a novel interaction mechanism known as “late interaction.”
ColBERT: Efficient and Effective Passage Search via Contextualized Late Interaction over BERT
The late interaction mechanism in ColBERT allows for efficient and precise retrieval by processing queries and documents separately until the final stages of the retrieval process. Specifically, ColBERT independently encodes the query and the document using BERT, and then employs a lightweight yet powerful interaction step that models their fine-grained similarity. By delaying but retaining this fine-grained interaction, ColBERT can leverage the expressiveness of deep language models while simultaneously gaining the ability to pre-compute document representations offline, considerably speeding up query processing.
ColBERT’s late interaction architecture offers several benefits, including improved computational efficiency, scalability with document collection size, and practical applicability for real-world scenarios. Additionally, ColBERT has been further enhanced with techniques like denoised supervision and residual compression (in ColBERTv2), which refine the training process and reduce the model’s space footprint while maintaining high retrieval effectiveness.
This code snippet demonstrates how to configure and use the jina-colbert-v1-en model for indexing a collection of documents, leveraging its ability to handle long contexts efficiently.
Implementing Two-Stage Retrieval with Rerankers
Now that we have an understanding of the principles behind two-stage retrieval and rerankers, let’s explore their practical implementation within the context of a RAG system. We’ll leverage popular libraries and frameworks to demonstrate the integration of these techniques.
Setting up the Environment
Before we dive into the code, let’s set up our development environment. We’ll be using Python and several popular NLP libraries, including Hugging Face Transformers, Sentence Transformers, and LanceDB.
For demonstration purposes, we’ll use the “ai-arxiv-chunked” dataset from Hugging Face Datasets, which contains over 400 ArXiv papers on machine learning, natural language processing, and large language models.
from datasets import load_dataset

dataset = load_dataset("jamescalam/ai-arxiv-chunked", split="train")

<pre>
Next, we’ll preprocess the data and split it into smaller chunks to facilitate efficient retrieval and processing.
from transformers import AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("bert-base-uncased")

def chunk_text(text, chunk_size=512, overlap=64):
tokens = tokenizer.encode(text, return_tensors="pt", truncation=True)
chunks = tokens.split(chunk_size - overlap)
texts = [tokenizer.decode(chunk) for chunk in chunks]
return texts

chunked_data = []
for doc in dataset:
text = doc["chunk"]
chunked_texts = chunk_text(text)
chunked_data.extend(chunked_texts)
For the initial retrieval stage, we'll use a Sentence Transformer model to encode our documents and queries into dense vector representations, and then perform approximate nearest neighbor search using a vector database like LanceDB.
from sentence_transformers import SentenceTransformer
from lancedb import lancedb

# Load Sentence Transformer model
model = SentenceTransformer('all-MiniLM-L6-v2')

# Create LanceDB vector store
db = lancedb.lancedb('/path/to/store')
db.create_collection('docs', vector_dimension=model.get_sentence_embedding_dimension())

# Index documents
for text in chunked_data:
vector = model.encode(text).tolist()
db.insert_document('docs', vector, text)

from sentence_transformers import SentenceTransformer
from lancedb import lancedb

# Load Sentence Transformer model
model = SentenceTransformer('all-MiniLM-L6-v2')

# Create LanceDB vector store
db = lancedb.lancedb('/path/to/store')
db.create_collection('docs', vector_dimension=model.get_sentence_embedding_dimension())

# Index documents
for text in chunked_data:
vector = model.encode(text).tolist()
db.insert_document('docs', vector, text)
With our documents indexed, we can perform the initial retrieval by finding the nearest neighbors to a given query vector.
from transformers import AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained("bert-base-uncased")

def chunk_text(text, chunk_size=512, overlap=64):
tokens = tokenizer.encode(text, return_tensors="pt", truncation=True)
chunks = tokens.split(chunk_size - overlap)
texts = [tokenizer.decode(chunk) for chunk in chunks]
return texts

chunked_data = []
for doc in dataset:
text = doc["chunk"]
chunked_texts = chunk_text(text)
chunked_data.extend(chunked_texts)
Reranking
After the initial retrieval, we’ll employ a reranking model to reorder the retrieved documents based on their relevance to the query. In this example, we’ll use the ColBERT reranker, a fast and accurate transformer-based model specifically designed for document ranking.
The reranked_docs list now contains the documents reordered based on their relevance to the query, as determined by the ColBERT reranker.
Augmentation and Generation
With the reranked and relevant documents in hand, we can proceed to the augmentation and generation stages of the RAG pipeline. We’ll use a language model from the Hugging Face Transformers library to generate the final response.
from transformers import AutoTokenizer, AutoModelForSeq2SeqLM

tokenizer = AutoTokenizer.from_pretrained("t5-base")
model = AutoModelForSeq2SeqLM.from_pretrained("t5-base")

# Augment query with reranked documents
augmented_query = query + " " + " ".join(reranked_docs[:3])

# Generate response from language model
input_ids = tokenizer.encode(augmented_query, return_tensors="pt")
output_ids = model.generate(input_ids, max_length=500)
response = tokenizer.decode(output_ids[0], skip_special_tokens=True)

print(response)
In the code snippet above, we augment the original query with the top three reranked documents, creating an augmented_query. We then pass this augmented query to a T5 language model, which generates a response based on the provided context.
The response variable will contain the final output, leveraging the external information from the retrieved and reranked documents to provide a more accurate and comprehensive answer to the original query.
Advanced Techniques and Considerations
While the implementation we’ve covered provides a solid foundation for integrating two-stage retrieval and rerankers into a RAG system, there are several advanced techniques and considerations that can further enhance the performance and robustness of the approach.
Query Expansion: To improve the initial retrieval stage, you can employ query expansion techniques, which involve augmenting the original query with related terms or phrases. This can help retrieve a more diverse set of potentially relevant documents.
Ensemble Reranking: Instead of relying on a single reranking model, you can combine multiple rerankers into an ensemble, leveraging the strengths of different models to improve overall performance.
Fine-tuning Rerankers: While pre-trained reranking models can be effective, fine-tuning them on domain-specific data can further enhance their ability to capture domain-specific semantics and relevance signals.
Iterative Retrieval and Reranking: In some cases, a single iteration of retrieval and reranking may not be sufficient. You can explore iterative approaches, where the output of the language model is used to refine the query and retrieval process, leading to a more interactive and dynamic system.
Balancing Relevance and Diversity: While rerankers aim to promote the most relevant documents, it’s essential to strike a balance between relevance and diversity. Incorporating diversity-promoting techniques can help prevent the system from being overly narrow or biased in its information sources.
Evaluation Metrics: To assess the effectiveness of your two-stage retrieval and reranking approach, you’ll need to define appropriate evaluation metrics. These may include traditional information retrieval metrics like precision, recall, and mean reciprocal rank (MRR), as well as task-specific metrics tailored to your use case.
Conclusion
Retrieval Augmented Generation (RAG) has emerged as a powerful technique for enhancing the capabilities of large language models by leveraging external information sources. However, traditional retrieval methods often struggle to identify the most relevant documents, leading to suboptimal performance.
Two-stage retrieval with rerankers offers a compelling solution to this challenge. By combining an initial fast retrieval stage with a more sophisticated reranking model, this approach can significantly improve the accuracy and relevance of the retrieved documents, ultimately leading to higher-quality generated responses from the language model.
I have spent the past five years immersing myself in the fascinating world of Machine Learning and Deep Learning. My passion and expertise have led me to contribute to over 50 diverse software engineering projects, with a particular focus on AI/ML. My ongoing curiosity has also drawn me toward Natural Language Processing, a field I am eager to explore further.


 Add Unite.AI to your preferred sources on Google